↓ Skip to main content

Who Resolves the Merge Conflict? Why the Bot and the Author Are Not Interchangeable

A pull request falls behind main and conflicts. Who resolves the conflict, the bot or the author? The answer depends on whether the conflict is mechanical or semantic, and treating the two as the same job is what makes every flat policy, “the bot rebases everything” or “the author handles it,” wrong.

The clean rebase is settled and out of scope; automate it on every push to main. The live question is the conflict, and the conflict is not one thing. Resolving a conflict means deciding what the code should now say, and that decision is a claim about what the author meant. Someone has to make it, and the interesting question is who can back it with intent they actually hold. The choice depends entirely on whether the conflict has a unique correct answer an oracle can check, or whether its correctness lives only in the author’s head.

Why the Question Got Loud
#

For most of git’s history the conflict question was quiet. A contributor resolved their own conflicts, or the maintainer did, and the round trip was short because the people involved shared a mental model of the code. Two things broke that equilibrium.

The first is auto-merge. Once low-risk changes land on green without a human clicking merge, a PR that cannot merge cleanly becomes the thing that stalls the whole lane. A human can absorb a conflicted PR by glancing and clicking; an automated merge pipeline cannot. Auto-merge makes conflict resolution a prerequisite of the lane, and that turns “who resolves” from a courtesy into a structural question.

The second is the model-authored pull request. When the author is a model, the conflict round trip behaves differently at both ends. The bot never sleeps, so a resolve request adds no latency the way it does for a human. But the bot also has no private knowledge of what the code was meant to do, so its resolution is a guess about intent presented as a fix. This is the plausibility problem, and it lands hardest exactly where the conflict is hardest.

So the modern repository has a lane that wants every PR mergeable on green, and a growing share of PRs whose intent lives only in the code a model produced, with no description, linked issue, or spec that states it independently. When the intent is encoded somewhere, a conflict has an oracle to check a resolution against. When it is not, there is nothing to verify the resolution by, and that, not the absence of an author to interrogate, is the actual problem. The old default, the contributor resolves, is too slow for the merge lane, and the bot is too confident to stand in as the oracle, so the live question is not who authored the PR but whether the intent exists outside someone’s head.

The Conflict Has a Gradient
#

Conflicts are not all the same, and the gradient is what lets you route them accurately.

At one end is the mechanical conflict: an import added in both branches, a trailing comma, two functions inserted at adjacent positions, a formatting drift the formatter can settle. Resolve it and there is exactly one answer any reasonable developer would accept, and a test suite that passes before will pass after. At the other end is the semantic conflict: two people changed the same logic for different reasons, and the correct resolution depends on which reason was right. The mechanical conflict has a unique correct answer that a test can falsify; the semantic conflict has no correct answer without the intent that motivated the change.

The mechanical conflict is therefore still logistics, just logistics that needs an oracle. Resolve it, run the suite, and if the suite passes the resolution is, by construction, the one the project already trusted. Here the test acts as the independent oracle the model cannot be, the same role it plays in closing the bug gap when a fix claims to be done. A conflict whose wrongness a test can catch is a conflict the bot may resolve, because the test, not the model, is signing off.

The semantic conflict is a different kind of problem. Nothing external is left to disagree with the model’s plausible stitch, because the definition of “correct” is the intent, and the intent is precisely what the model does not have. A bot that resolves a semantic conflict is making an intent claim it cannot source, and the harder the disagreement, the more likely the claim is a confident fabrication.

Where the Intent Lives
#

The semantic conflict splits once more, and it splits on a cleaner axis than who wrote the PR: whether the intent is encoded anywhere a resolver can read it.

Intent can live in two places. It can be encoded, written down in the PR description, a linked issue, an acceptance criterion, a failing test, anything a human authored to state what the change was supposed to do. Or it can be tacit, held in someone’s head and never written down, surfacing only if you ask. A conflict is safe for the bot to resolve when the intent is encoded and the encoded source covers the disputed region, because then the resolution has an oracle. It is not safe when the intent is tacit, because then nothing external can falsify the bot’s stitch, and the stitch will look right whether or not it is.

Author type matters, but only as a proxy for where the intent lives, and the proxy is worth stating because it inverts the naive assumption.

When the PR is human-authored, the human’s own description is an independent statement of intent. If the description covers the conflict, the bot may resolve against it, and the description, not the model, is the oracle. If the description is thin or silent on the disputed region, the intent is effectively tacit, and the only defensible move is to ask the human who holds it.

When the PR is bot-authored, the trap is that the bot’s description is not an independent oracle. It was written by the same model that wrote the code, or a sibling of it, so checking the resolution against the description is checking the model against its own narration, which provides no real verification. The only trustworthy intent source for a bot-authored PR is something a human wrote upstream: the issue, the spec, the prompt, an acceptance test. When that upstream source exists and covers the conflict, the bot may re-derive against it, and the re-derivation is checkable. When it does not exist, the intent was never encoded by anyone, and the bot’s resolution is a guess about intent no one ever wrote down.

This is the refinement the flat “maintainer picks a default” framing misses. A single repository-wide default is too coarse, because the right default is a function of whether the PR carries an encoded, independent intent source, and that varies PR by PR, not repository by repository. The PR that links a human-authored issue with acceptance criteria is safe for bot resolution regardless of who wrote the code; the PR that arrives as code and a self-description is not safe regardless of who wrote the code.

The Label Is the Right Mechanism, the Default Is the Question
#

Given the split, the mechanism worth reaching for is the one the question already points at: a label on the PR that decides who resolves a conflict. Labels are already how a modern triage layer expresses every other routing decision, and conflict resolution is no different in kind. The label should express the thing that actually varies, which is not “is this PR rebased” but “who is allowed to resolve a semantic conflict on it.”

For a mechanical conflict there is no decision worth encoding: the bot resolves, the test gates, and a conflict: auto-resolved note is enough audit trail. The label is worth having at the semantic tier. Something like conflict: author-resolves versus conflict: bot-may-resolve, defaulted per repository by the maintainers and overridable per PR, is the right form, and it is the form the question proposes.

The interesting work is in the default, and the sound default routes on intent availability, not on author type. A PR that links a human-authored issue or spec, with acceptance criteria that cover the change, defaults to bot-may-resolve, because the resolution has an oracle. A PR that arrives as code alone, with no independent statement of intent, defaults to author-resolves, because nothing can falsify the bot’s stitch. The maintainer’s real choice is not “auto or manual.” It is “what do we assume about a PR whose intent source we cannot verify.” The conservative answer, treat the PR as unencoded and ask the author, costs a little latency where the bot could have handled it. The permissive answer, resolve and trust the model, costs intent claims that are silently wrong. Between losing a little speed and shipping a confidently wrong merge, the speed is the cheaper loss, so the default for a PR with no verifiable intent source should be author-resolves.

This makes the highest-leverage change a documentation change, not a tooling one. Require, in the pull request template, a linked issue or a short intent statement that covers the change, and ask whether the PR was model-assisted. The linked issue turns an unencoded PR into an encoded one; the model-assisted flag tells you whether the PR’s own description can serve as an oracle or whether you need the upstream source. Both shrink the “no verifiable intent” bucket, and shrinking that bucket is what lets the auto-merge lane actually run.

What to Do Next
#

First, surface the conflict instead of hiding it. Add eps1lon/actions-label-merge-conflict so any PR that falls behind main gets a merge-conflict label the moment it conflicts, and loses it the moment it merges again. Your auto-merge lane can now filter -label:merge-conflict and only act on work that is actually ready. The author gets an automated nudge that a real decision is needed, without you being the one to say it.

Second, classify the conflict before you route it. Mechanical conflicts (imports, formatting, adjacent non-overlapping edits) go to the bot behind the test gate, and the test is the oracle that makes the resolution trustworthy. If the suite fails, the resolution is wrong by definition and the bot escalates rather than ships.

Third, route the semantic conflict by whether an independent intent source exists. If the PR links a human-authored issue or spec that covers the disputed region, let the bot resolve and check the result against that source, with an encoded test that must pass on the resolved tree. If the PR carries no such source, post the conflict as a comment and drop the PR to author-resolves until someone provides the intent or resolves it by hand.

Fourth, choose the conservative default for the case where you cannot tell. When a PR arrives with no linked issue and no intent statement, default to author-resolves, because the cost of a confidently wrong merge is higher than the cost of a round trip, and the round trip at least asks the question the silent resolution skips.

Fifth, make the routing signal cheap to produce. Require a linked issue or a short intent statement in the pull request template, and ask whether the PR was model-assisted. The link is what turns an unencoded PR into an encoded one, and the model-assisted flag is what tells you whether the PR’s own description can count as the oracle.

Do not write a policy that says “the bot resolves everything” or “the author resolves everything.” Both are the original mistake in policy form. Gate the mechanical conflict behind a test, defer the semantic conflict to an independent intent source when one exists, and defer to the author when one does not.

See also
#

  • Triaging Open Source Pull Requests - the upstream layer this refines: labeling merge conflicts and routing by risk is the triage move, and conflict-tier routing is what makes the auto-merge lane inside that layer safe
  • The Merge Gate - the case for gating on the properties of a change rather than on the existence of a PR, which is the same principle applied here to “is this a mechanical conflict or a semantic one”
  • The Acceptance Gap: Why an LLM Solution Is Not a Shipped Solution - why a conflict resolution is a mini-acceptance gap: the mechanical tier wants a check (verification), and the semantic tier wants the author’s reaction (validation)
  • Rethinking Code Review in the Age of LLMs - the plausibility problem in full, the reason a bot resolving a semantic conflict is making a claim about intent it cannot source

Feature Parity Is Not a Moat: Compete on What Does Not Clone

For most of software’s history, shipping a feature bought you a window. A competitor had to understand the need, design the thing, build it, test it, and ship it. That took weeks or months, during which you could compound users, data, and trust. That window has collapsed to days, sometimes hours, and the uncomfortable implication is that the feature was never the moat. The slowness of copying it was. Once the copying is nearly free, every hour spent perfecting a feature is an hour spent on the one layer the market just commoditized, and the advantage has moved somewhere developers were trained to undervalue.

The Moat Was Always Somewhere Else
#

An economic moat is the structural thing that lets a business keep its profits against competitors. The standard list of what counts as one is telling: switching costs, network effects, cost advantages, intangible assets like brand and patents, and efficient scale. A feature is not on that list. A feature is something you build in the hope that a moat forms around it, through usage, data, or habit, before anyone else arrives.

For a long time the list and the feature felt like the same thing, because copying was slow. You shipped the recommendation engine, and by the time a rival reverse-engineered it, your users had generated enough behavior to make yours better. You shipped the dashboard, and by the time it was cloned, your customers had wired it into their weekly review and would not move. The feature was the seed, and the copy-time was the growing season, and the moat was the harvest. The copy-time is gone, which means the growing season is gone, which means a feature shipped with no other plan now arrives at the market with no moat attached.

What Actually Clones, and What Does Not
#

It is worth being clear about the boundary, because the claim is not that everything is copyable.

What clones easily is the surface. The visible feature, the UI flow, the API surface, the integration that calls a public endpoint, the report that joins two tables. A capable engineer with an LLM can reproduce any of these from a screenshot or a description in an afternoon, and a competitor can ship a credible copy in a week. The commoditization of the application layer is real, and it is fast.

What does not clone is everything that had to be true for the feature to be valuable in the first place. The two years of usage data that makes the recommendation correct. The thousand integrations already in your customers’ workflows. The track record of reliability that makes a procurement officer sign. The deep, specific knowledge of a narrow industry that lets you pick the right feature to build next. The competitor can copy the feature and still be left holding an empty shell, because the value was never in the shell. It was in the data, the relationships, and the context the shell was built to carry.

Where the Moat Moves
#

When the feature stops being the moat, the advantage moves to the layers that surround it, and almost all of them are things that compound through time rather than through code. Five of them matter for a developer deciding where to spend next quarter.

The learning loop, not the feature
#

The competitor copies your feature, but they do not copy what you learned by shipping it. Shipping a feature in front of real users tells you which half of it was wrong, which edge case matters, and which adjacent problem is now the real one. That knowledge is yours alone until competitors run the same experiment themselves, and they will now run it by copying your result rather than discovering their own. The moat is the build-measure-learn cycle compressed to days, run against real users, faster than anyone who is copying can run it. A feature is no longer a deliverable; it is a probe, and the team that runs more probes per month learns more about the market than the team that ships fewer, more perfect features.

Proprietary data and feedback
#

A clone of your feature without your data is a weaker feature. The recommendation is bland, the search results are generic, the anomaly detection fires on the wrong things, because the model behind the clone has nothing the field has not already seen. Every interaction with a real user adds signal to your data that the clone cannot synthesize, and this compounds quietly until the gap is not closeable by better code. This compounding is the mechanism behind network effects, and it is one of the few things that genuinely does not clone.

Workflow depth and switching costs
#

A feature you can use in a minute is a feature you can leave in a minute. A feature that is wired into six other systems, that holds three years of configuration, that your team’s runbook depends on, is a feature that survives a cheaper clone because the cost of moving exceeds the cost of staying. These switching costs are a legitimate moat when they are a side effect of genuine usefulness, and they are built by going deep into the customer’s workflow rather than wide across a feature checklist. Shallow integrations clone in a day; deep ones do not, and depth is a function of how much of the customer’s actual job you have absorbed.

Distribution, brand, and trust
#

Engineers historically treated these as someone else’s problem, which was always a mistake and is now an expensive one. The feature that arrives through a channel the user already trusts, from a name they recognize, beats the marginally better clone that arrives cold. Trust is built slowly, through reliability and through presence, and it is one of the slowest things in the product to reproduce. A developer who invests zero attention here has chosen to compete purely on the layer that clones fastest.

Judgment about what to build
#

Judgment is the layer the rest of this blog keeps arriving at, because the bottleneck keeps moving toward it. When everyone can build anything, building things stops being the differentiator, and deciding which thing to build, for whom, and in what form becomes the whole game. That judgment is a personal and team-level moat, it compounds with practice, and it does not clone because the competitor cannot copy the years of being close to the problem that produced it.

The Feature Race Is a Trap
#

The failure mode to avoid is the feature-parity race, and it is the default response if you do not see the shift.

You ship a feature, the competitor copies it, you ship another to pull ahead, they copy that, and the cycle repeats. Both teams are running as fast as they can and neither is building a moat, because every feature is neutralized within a week of landing. You are exhausting yourselves producing advantages that confer no advantage, and the only thing accumulating is technical debt from features nobody had time to integrate properly.

The feature-parity race is the same trap as first-mover advantage misunderstood. Being first was valuable only because first movers got the growing season, the time for data and habit to form before the copiers arrived. When the growing season disappears, being first stops being the point. Being the one who learns fastest from being there is the point.

The deeper error is treating the feature list as the scoreboard. It feels like progress, because the features keep shipping and the release notes keep growing. But a competitor watching your changelog now has your roadmap for free, and a model lets them execute it at your speed. A changelog is no longer a strategic asset; in a clonable world it is a blueprint you hand to your competitors every week.

What to Do Next
#

A few concrete moves follow from treating features as probes and moats as the target.

Audit where your engineering effort actually lands. If the large majority sits on building and polishing features, you are over-invested in the layer that clones and under-invested in the layers that do not. Reallocate deliberately, not by abandoning features, which you still have to ship, but by capping the time each feature gets and routing the surplus into data, integration depth, and the learning loop.

Instrument every feature as an experiment from day one. If you ship a feature and cannot tell within a week whether it moved the metric you built it for, you have shipped a deliverable, not a probe. You have also given up the one advantage the copy does not get. The measurement is the moat, because it is what turns the feature into learning the competitor does not inherit.

Pick a narrow domain and go deep rather than spreading wide. The competitor who clones your broad, shallow surface gets a credible copy. The competitor who tries to clone your deep, specific understanding of one industry’s workflow has to do the years of work you already did, and most will not bother. A moat that survives cloning is built from depth.

Invest in the layers engineers usually skip. Distribution, documentation that lives where users find it, reliability that earns trust, onboarding that makes the product sticky through genuine usefulness rather than lock-in. These compound while features are being copied, and they are the reason the copy arrives to an empty room.

And protect the judgment layer on your own team. The skill of deciding what to build is now the highest-leverage skill a developer can hold, and it is built by staying close to users, not by staying close to the IDE. Delegate the building aggressively so that the time you reclaim lands on the judgment, the data, and the relationships, because those are the three things the clone will never contain.

The Moat Moved
#

The feature stopped being the moat the day it became cheap to copy. That shift is not a threat to the developers who notice, because the moat did not disappear; it moved to a set of layers that reward exactly the attention most engineers have been trained to underinvest in. Data, distribution, workflow depth, trust, and judgment all compound, and none of them clone.

The teams that win this era will still ship features, because they have to. They will just stop treating the features as the point. The feature is the seed; the moat is the growing season, and the growing season is now made of everything except the code.

See also
#

References
#

  • Economic moat - the structural sources of sustained advantage, the canonical list against which a feature is revealed to be a seed rather than a moat
  • Commoditization - what happens when a previously differentiated layer becomes cheap and standard, which is what happened to the application feature layer
  • Switching barriers - the workflow-depth moat that does not clone, built by absorbing more of the customer’s actual job
  • Network effect - the data-and-usage moat that makes a clone strictly weaker than the original it copied
  • Lean startup - the build-measure-learn framing that turns a feature from a deliverable into a probe, the learning loop that outpaces copying
  • First-mover advantage - why being first was only valuable during the growing season, and why that advantage compresses as copy-time collapses

The Acceptance Gap: Why an LLM Solution Is Not a Shipped Solution

Generation is solved. You describe, the model produces, and the candidate looks plausible in seconds. The bottleneck is no longer producing a solution; it is deciding that a solution is acceptable, and that gap is the one the model cannot close on its own.

I keep noticing the gap in two forms, and they fail for different reasons, which is why a single strategy like “review the output” addresses neither one well. One is a bug fix that the model swears it fixed and did not. The other is a feature that meets the description and still is not what I wanted. Both feel like the model failed, but the failure is in a different place each time, and the difference is the whole point.

The Gap Is Not One Gap
#

The distance between “a description of what I want” and “an acceptable solution I would ship” is not a single gap. It is two, stacked, and they respond to completely different interventions.

The first gap is about correctness. Did the change do the thing it was supposed to do, in the world, against ground truth the model cannot see? The second gap is about fit. Does the result match the thing I actually wanted, most of which I never wrote down?

Correctness is, in principle, objective. You can check it. Fit is, in practice, subjective. You can only feel it.

Most of the frustration people report with LLM coding comes from treating these two gaps as the same gap, and applying the tool that closes one to the other. The bug gap wants a check; the feature gap wants a reaction, and reaching for one when you need the other is why the work keeps coming back unfinished.

Bug Fixes: The Silent-Failure Gap
#

When I ask an LLM to fix a bug, it returns a patch that looks correct. It will explain the root cause in a confident voice, write a plausible diff, and tell me the issue is resolved. Often it is. Sometimes the patch addresses a symptom and the root cause resurfaces next week. Sometimes it fixes the exact reproduction I pasted but not the general case. Sometimes it fixes nothing at all, and merely rearranges the code into something that looks like a fix.

The model cannot tell me which of those happened, because the model has no access to the ground truth that would let it verify its own claim. It optimized for “a plausible fix,” not for “a verified fix.” Its confidence is not evidence, and nothing in the tone of the output distinguishes a real fix from a convincing one.

This is the dangerous kind of failure, which testers have always called the oracle problem: without an independent way to decide what the correct output is, you cannot tell that a plausible output is wrong. The model has the problem in its most acute form, because it is both the thing producing the answer and the thing narrating why the answer is right. The narrator is not independent of the guess.

So for bug fixes I end up verifying manually. I reproduce the original failure, apply the patch, and check whether the failure is gone. Not because I enjoy the step, but because the model’s report of “fixed” is a hypothesis, not a result. A fix is not fixed until something independent of the model says so.

Features: The Taste Gap
#

When I ask an LLM to build a feature, the gap is different, and it fails for a different reason.

The feature works, in the narrow sense that it does what the description said. The gap is that “meets the description” is not “matches what I wanted,” because most of what I wanted was never in the description. It lived in taste. The feel of the interaction. The expectation about a default. The sense that this control belongs here and not there, that the empty state should say this and not that, that the feature is finished when it feels light rather than heavy.

I did not write any of that down, because I did not know I wanted it until I saw the result that lacked it. This is the nature of subjective requirements: they are discovered by contact with the artifact, not enumerated in advance. A specification can carry the objective part of what you want; it cannot carry the taste, because the taste is a reaction you have not had yet.

So the loop for features is not “verify,” it is “try.” Generate, run it, notice the distance between what I got and what I expected, describe that distance, regenerate. When the distance closes to zero, I stop. That stopping point, the “just ship it” moment, is a taste judgment, not a verification step. No test defines it. I define it, by being satisfied.

Why the Model Cannot Close Either Gap Alone
#

The two gaps look different, but they share one cause. Both are acceptance gaps, and acceptance requires information the model does not possess.

For bugs, the missing information is the ground truth of correct behavior. That truth lives outside the model, in an executable check or in a human observation. The model can guess at it, but it cannot consult it. For features, the missing information is my taste. That lives outside the model too, in the reaction I will have when I try the result. The model can guess at it from my description, but it cannot feel it.

In both cases the model can generate candidates freely, and in both cases it cannot sign off on them. Signing off requires exactly the external information that was never in the prompt, which is why no amount of rephrasing the prompt closes the gap.

This is the same pattern I described in The Shifting Bottleneck: automating a layer does not remove the layer, it moves the constraint to the layer above it. Here the automated layer is generation, and the layer above it is acceptance. The work did not go away. It turned into deciding whether the generated thing is good enough.

What Closes Each Gap
#

The two gaps respond to different interventions, and the strategy is to match the intervention to the gap.

The bug gap is closeable in principle, and the mechanism is encoding. Write the acceptance criterion as a check the model cannot fake. A failing test that must pass. A reproduction script that must go green. A property the output must satisfy, stated before the fix is written. Once the check exists, the model can run it, and its claim of “fixed” becomes trustworthy only when the check agrees. The bug gap shrinks to exactly the set of bugs for which I have not yet written a check.

This is test-driven development, rediscovered as the answer to “why don’t I trust the model’s fix.” The discipline is to write the check before, or alongside, the fix, not after. A bug fixed without a check is a bug I will have to verify by hand, forever, because nothing is keeping it fixed. A bug fixed with a check stays fixed, because the check fails loudly if the bug regresses, whether or not I am looking.

The feature gap is not closeable the same way, and this is the uncomfortable part. I cannot write a test for “this feels right,” because I do not know the specification of my own taste until I see the result. Exploratory testing and specification by example help me surface more of what I want, but they cannot surface all of it, because the residual is a reaction, not a requirement. The feature gap closes only through iteration, and the terminal condition is a human saying “good enough, ship it.”

There is no encoding that removes the human from the feature loop, because the human’s reaction is the signal the loop is measuring. The best I can do is make the loop fast, so that each try is cheap and I can afford many of them. A model that generates in thirty seconds and an environment where I can try the result in ten more is a loop I can run ten times in a morning, and the tenth version is usually the one I ship.

The Mistake Is Treating Them as the Same Gap
#

Most of the waste in LLM-assisted work comes from applying the wrong tool to the wrong gap.

Treat the taste gap as a verification problem, and you write tests that pass and ship features nobody likes. The tests confirm the feature does what the spec said, which was never the question. The question was whether the spec was the right spec, and no test answers that.

Treat the verification gap as a taste problem, and you manually re-check, by hand, things the model could have checked for itself. You read a diff looking for whether the bug is really fixed, applying your eyes as a slow and unreliable oracle, when a failing test would have answered in a second and answered the same way every time. You burn the attention you should have been spending on taste on work the model could have done for you.

The split is sharp once you see it. If the gap is “did it do the thing,” that is a check, and the move is to encode the check so the model runs it without you. If the gap is “is this the thing I wanted,” that is taste, and the move is to iterate fast and trust the stopping judgment. Verification and validation are the old words for this distinction, and they have never been more useful than they are now: verify against the spec, validate against the want. The model can help with the first. It cannot do the second for you.

What to Do Next
#

Sort the next ten things you hand to the model into two piles.

The bug pile gets a check for each item, written first. If you cannot write a check that would fail before the fix and pass after it, you do not yet understand the bug well enough to delegate it, and the model’s fix will be a guess you have to verify by hand anyway. The check is the thing that makes delegation safe.

The feature pile gets a fast iteration loop. Cut anything that slows down the try-it-and-react cycle, because the cost of a feature is no longer the cost of building it, it is the cost of the number of tries it takes to match your taste. A model that builds cheaply makes many tries affordable, and that is the real lever.

Leave the “is this good enough to ship” judgment to yourself. Generation is no longer the bottleneck, and neither, soon, is verification, once you encode it. The bottleneck is acceptance, and the half of acceptance that is taste is the last compounding thing you do. Nobody can write that prompt for you, which is exactly why it is the part worth keeping.

See also
#


llm-augmented-workflows - A config-driven automation engine for GitHub, powered by opencode

GitHub ships a perfectly good event bus. Issues get opened, labeled, and closed; PRs get reviewed and merged; comments land on lines and threads. Every one of those events is a chance for an LLM agent to do useful work, triage the issue, draft a plan, reproduce a bug, post a review. The gap is not the events and it is not the agents. The gap is the glue between them.

Today that glue is per-flow YAML. Every workflow you want to automate gets its own triage.yml, plan.yml, implement.yml, each with its own copy of the agent invocation boilerplate, its own trigger, its own label math, and its own drift. Add a fourth flow and you copy the file again. Change how the agent is called and you edit all of them. The workflows describe the same agent doing different things, but they share nothing.

I built llm-augmented-workflows to collapse all of that into one file. You describe every flow as event-matched rules in a single .github/llmaw/flows.yml, and the dispatcher routes GitHub events to the right agent skill, with token-free label and shell steps for the transitions that do not need a model.

The problem
#

The moment you try to automate more than one agent-driven flow, the per-file pattern buckles.

Each flow duplicates three things it should not. First, the wiring: trigger on this label, run the agent, relabel, wait for the next event. Second, the agent invocation: which model, which skills repo, which timeout, which working directory. Third, the outcome handling: what to do when the agent says approved, rejected, or needs changes.

That duplication is not free. Workflows drift from each other. The agent invocation that worked yesterday is copy-pasted into the new flow with the old model id. A label rename in one file does not propagate to the others. And the parts of the flow that do not even need an LLM, relabeling an issue, posting a canned comment, closing a linked issue on merge, still pay for a model call because that is what the file is built around.

What you want is to describe the flow once, and let the engine handle the wiring.

How it works
#

The engine is a small stateless dispatcher with one reusable GitHub Actions workflow. State lives entirely in GitHub, in labels, issues, and PRs. The engine reads an event, matches it against flows.yml, runs the matched rule’s pipeline, and exits.

GitHub event (issue labeled, PR merged, comment, ...)
   |
   v
dispatch.yml  reads flows.yml  ->  route matches rule(s)
   |
   v
for each matched rule, run-rule runs its whole `run` in one pass:
   labels/shell (pre) -> skill (opencode) -> labels/shell (post) -> on_outcome
   |
   v
the agent acts on GitHub (relabel, comment, open PR, close) -> emits new events

The pipeline is the unit of work. A rule’s run is an ordered list of steps, and the engine runs them in one pass: token-free label and shell steps can run before and after the agent, the agent step calls an opencode skill, and on_outcome maps the agent’s verdict to labels, a close, or a comment. Because relabeling emits a new event, the next phase of the flow is just another rule that matches the new label. Terminal outcomes emerge naturally: an agent closes an issue (won’t fix), or a PR merges and an on-merge rule closes the linked issue.

One config file, not one workflow per flow
#

Every flow lives in .github/llmaw/flows.yml. A flow is a list of rules, and a rule is a when (the event match) plus a run (the ordered pipeline).

defaults:
  model: opencode/deepseek-v4-flash-free
  agents_repository: tomzx/agents
  timeout_minutes: 30
flows:
  plan:
    rules:
      - id: generate-plan
        when: { event: issues, action: labeled, label: plan-needed }
        run: [ { skill: generate-plan } ]
      - id: on-plan-merged
        when: { event: pull_request, action: closed, merged: true, branch_prefix: plan/ }
        run: [ { labels: { add: [plan-approved], target: linked-issue } } ]
      - id: implement
        when: { event: issues, action: labeled, label: plan-approved }
        run: [ { skill: implement-plan } ]

Read it top to bottom and that is the whole flow. An issue gets plan-needed, the generate-plan skill runs and opens a plan/... PR. When that PR merges, on-plan-merged adds plan-approved to the linked issue, no model involved. When the issue is labeled plan-approved, the implement-plan skill runs and implements it. Three rules, one file, one copy of the wiring.

Token-free transitions
#

Token-free transitions are the feature that pays for the whole design.

Relabeling an issue does not require an LLM, and neither does closing a linked issue on merge or posting a deterministic comment. In llm-augmented-workflows, labels and shell steps run without calling the model at all. The on-plan-merged rule above is a single label step: when the plan PR merges, add plan-approved to the linked issue. Zero tokens, zero model latency, just a GitHub API call.

That means the agent only runs where the agent is actually needed, and the transitions between phases are free, fast, and deterministic. A flow that used to cost three model calls (triage, plan, implement) plus the glue between them now costs two, because the glue is a label.

Two execution modes
#

Each matched rule’s pipeline runs in one job. What happens after the pipeline is controlled by the execution mode:

  • event-driven (default): the rule runs once and the job ends. The relabel emits a new event that re-triggers the dispatcher for the next phase. One job per phase, each one independently observable in the Actions log.
  • continuous: the same job keeps advancing to the next rule based on the labels each rule adds, until llmaw:needs-human appears or the chain reaches a resting state. One job per pipeline, the whole end-to-end run in one log.

Set it under defaults.execution or per flow, force it per dispatch via the execution input or the LLMAW_EXECUTION repo variable. Event-driven is easier to debug; continuous is easier to watch flow end to end. The same flows.yml works in either mode, because the mode is about how the engine chains rules, not how the rules are defined.

Skills come from your agents repository
#

The skill step does not run an inline prompt. It runs an opencode skill sourced from a configurable agents repository, tomzx/agents by default, overridable with AGENTS_REPOSITORY.

That separation matters. The flow definition says what should happen and when. The skill definition says how the agent should do it. When you improve the generate-plan skill, every flow that references it gets the improvement, without touching flows.yml. When you add a new flow, you reference an existing skill instead of inlining a prompt that will drift.

The default flow runs on the free model
#

The default model is opencode/deepseek-v4-flash-free, and it needs only the auto-provided GITHUB_TOKEN. You can adopt the engine on a throwaway repo without provisioning a single secret. Override per repo or per org with OPENCODE_MODEL, point AGENTS_REPOSITORY at your own skills, raise LLMAW_MAX_ITERATIONS for long continuous runs, and you are done.

Getting started
#

Three steps.

  1. Add one wrapper workflow to your repo, pinning the dispatcher by ref.

    .github/workflows/llm-workflows.yml

    name: LLM Workflows
    on:
      issues: { types: [opened, labeled, reopened, closed] }
      pull_request: { types: [closed, labeled, ready_for_review] }
      issue_comment: { types: [created] }
      pull_request_review_comment: { types: [created] }
    permissions:
      contents: write
      pull-requests: write
      issues: write
    jobs:
      dispatch:
        uses: TomzxCode/llm-augmented-workflows/.github/workflows/dispatch.yml@v1
        secrets: inherit
  2. Add .github/llmaw/flows.yml describing your flows. Start from the example above or the docs/flows.md recipes for triage, close-on-merge, and per-step overrides.

  3. Run the Setup Labels workflow to create the labels declared under labels:, or let your flows add them as needed.

Pin @v1 for the latest within a major tag, @main if you want to track the tip, or @<full-sha> for an immutable production pin.

Consumers never copy the engine. The dispatcher checks this repository out into .llmaw/ on the worker and runs uv run --project .llmaw llmaw ..., pinning the version via the wrapper’s uses: ref.

What it does not do yet
#

The engine’s unit of work is one issue per workflow execution. A matched rule runs, the agent acts, the job ends (or chains within continuous mode until needs-human), and the next event is the next run. That model maps cleanly onto small, well-scoped work: triage this issue, plan this feature, reproduce this bug, implement this task.

It does not map onto a large epic. A change that spans many tasks, many PRs, and many days cannot be implemented by a single issue’s pipeline, because the engine has no concept of an epic as a first-class object that owns child issues and tracks their aggregate progress. To implement a large change today, you have to break the epic into per-task issues yourself, outside the engine, and let each of those issues run its own one-issue pipeline. The decomposition step, deciding how to split the work and how the pieces depend on each other, is not automated.

Closing that gap is the next phase of the problem, and it is where the needs-human checkpoint currently has to do the most work. Until the engine can take an epic, decompose it into ordered tasks, and drive each task through its own run while tracking the whole, large changes stay a manual decomposition followed by automated execution.

Why this structure
#

I have been writing about the pieces of this for a while. Loops as Files argued that the trigger layer deserves the same treatment as the prompt layer, versioned, reviewable, owned next to the behavior it schedules. The Self-Evolving Repository pushed the question of how far you can take a GitHub project where every maintainer function is replaced by an automated loop. llm-augmented-workflows is the engine for both: the flows file is the schedule, the skills are the behavior, and the state never leaves GitHub.

If you already use ghx for agentic code reviews or github-board to visualize your issues, llm-augmented-workflows is the layer that makes the issues move on their own.

See also
#

  • Loops as Files - the scheduling layer that flows.yml makes concrete per repository
  • The Self-Evolving Repository - the end state this engine is built toward
  • ghx - the CLI the review skills use for inline PR comments the gh CLI does not expose
  • github-board - a kanban view over the same GitHub state these flows mutate
  • The Merge Gate - why the human checkpoint (llmaw:needs-human) stays in the loop

github-board - A kanban board for any GitHub search

GitHub’s issue and PR lists are flat. When you’re tracking a dozen repositories, or triaging hundreds of items, a flat list stops being a useful view of your work. GitHub Projects exists, but it demands manual triage and won’t adapt to an ad-hoc layout you want for the next ten minutes.

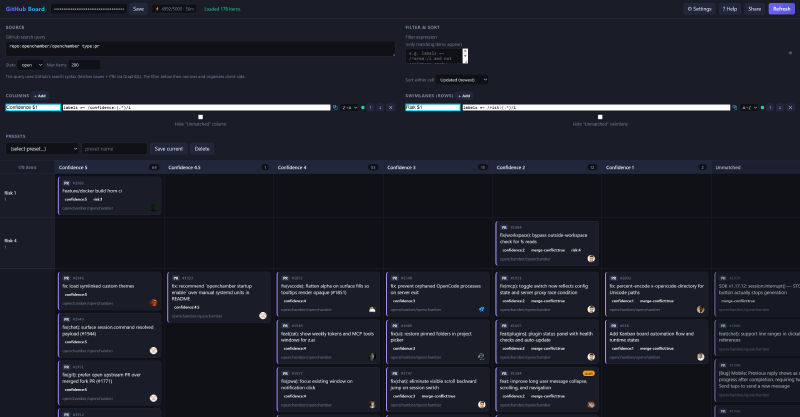
I built github-board to fix this. It turns any GitHub search into a customizable kanban board, defined entirely by small filter expressions. There is no backend, no build step, and no framework. You open index.html in a browser, paste a token, and sketch a board in seconds against live data. Try it live at tomzxcode.github.io/github-board.

github-board overview

The problem
#

A GitHub issue list answers one question well: what is in this repo, in this state. It answers almost every other question poorly. Which of my open PRs are drafts, which are waiting on review, and which have gone stale? How are issues spread across the area:* labels? What does the backlog look like across an entire organization?

You can build a GitHub Project board to answer these questions, but each card has to be placed and maintained by hand. The board reflects triage you did, not the state of your data right now. For a recurring view that’s worth the effort. For a one-off question you want to answer in 30 seconds, it isn’t.

How it works
#

You give github-board a search query, the same syntax the GitHub search bar already understands.

repo:owner/name

Then you define columns with boolean expressions over the fetched items. The board fetches up to 2000 issues and PRs through the GraphQL API with pagination, then groups them into columns entirely in your browser.

A default board ships with Draft PRs, Open PRs, Open Issues, and Closed columns. Each column is just an expression, and the board re-renders live as you type.

Columns and swimlanes as expressions
#

Every column is a filter expression against fields like type, state, labels, assignees, and dates.

type:pr and state:open and draft
type:issue and state:open and label:bug
state:closed and updated > -7d

The expression language supports the operators you’d expect: ==, =~, <, contains, in, exists, empty, plus regex matching and relative date math like -7d, -2w, -1y.

You can add a second dimension with swimlanes (rows), so a board can group issues by assignee across the same set of status columns, all from one query.

Auto-split with a $1 capture
#

Auto-split is the feature I use most. If you put a $1 capture in a column or lane rule, github-board expands it into one bucket per distinct matched value.

Name a lane area:$1 matching labels =~ /area:(.*)/i, and you instantly get one row per area label that exists in your data. Name a column the same way and you get one column per label. No manual setup per bucket, and buckets with no items simply don’t appear or stay empty depending on your preference. The $1 capture is the fastest way to see how work distributes across a category you didn’t know you cared about until just now.

Shareable links and presets #

The entire view (query, filter, columns, swimlanes, and sort) is encoded in the URL hash. Click Share, send the link to a teammate, and they see your exact board using their own token. The token is never included in the link, so you can paste it anywhere.

For boards you return to, save the full configuration as a named preset. Presets persist in localStorage alongside your token, so everything stays in your browser.

Privacy and scope
#

github-board is read-only and has no backend. Requests go directly from your browser to api.github.com. You bring your own personal access token, which is stored only in your browser’s localStorage. There is no OAuth flow, no server logging, and no way for the tool to modify your issues or pull requests.

github-board is a view, not a project-management tool. There is no drag-and-drop across columns, because the source of truth is your data, not where a card was dropped.

Getting started
#

No install is required.

  1. Open tomzxcode.github.io/github-board (or open index.html from the repo).
  2. Paste a GitHub personal access token with read access to what you want to view.
  3. Open Settings and enter a query like repo:owner/name or org:your-org.
  4. Click Refresh and adjust the columns to match your workflow.

If you already use gh-cached to browse issues without burning your rate limit, or ghx for agentic code reviews, github-board is the visual counterpart: the same GitHub data, arranged the way you want to see it right now.

See also
#

  • gh-cached - browse GitHub issues and PRs from a local cache to avoid rate limits
  • ghx - a CLI for the inline comment and review operations the gh CLI doesn’t expose
  • Triaging open source pull requests - the kind of high-volume review work github-board is built to visualize
  • Backlog management best practices - principles for keeping a backlog scannable that expression-driven boards make concrete

Defects Flow Downstream, Fixes Must Flow Upstream

The further upstream a defect is born, the more code it contaminates, and the more expensive it becomes to remove. This has been true for as long as software has had a lifecycle. Two things have changed, and both point the same way. First, the generation step is now automated, so upstream defects are materialized downstream at machine speed. Second, the old habit of patching defects in place no longer buys what it used to. Once the pipeline executes itself, the only durable fix is the one made at the source, and every fix made downstream is a patch you will have to make again.

The Pipeline Has Always Run One Way
#

Software development is a cascade. Each stage constrains the next: needs become requirements, requirements become a specification, the specification becomes an architecture, the architecture becomes code, the code is verified, shipped, and operated. A decision at any stage narrows the space of what is possible at every stage below it, and an error at any stage is inherited by everything that descends from it.

This directionality is why the cost of removing a defect rises so steeply the later you find it. Boehm and Basili put a number on it more than two decades ago: finding and fixing a software problem after delivery is often a hundred times more expensive than finding and fixing it during requirements and design. The exact multiplier is debatable, but the slope of the curve is not. Each stage a defect survives multiplies its removal cost, because each stage builds artifacts on top of it that all have to be reworked when the foundation moves.

The industry already has a name for the obvious response. It is called shift-left testing, and the move it prescribes, pushing verification earlier in the lifecycle, is correct as far as it goes. But shift-left is a half-measure, because it moves the act of checking earlier without moving the act of fixing to where the defect was born. The deeper move is not “test earlier.” It is “fix at the origin,” and the two are not the same. Testing earlier finds the symptom sooner; fixing at the origin ensures the symptom is never generated again.

The Amplifier Got an Engine
#

Before LLMs, a human wrote the code, and the human was a lossy interpreter of the specification. That lossiness was quietly essential. When the spec was ambiguous, the human made a judgment call, often a reasonable one, and that judgment absorbed some of the upstream defect before it could reach the running system. The defect still propagated, but through a mind that could correct it on the way down.

The model does not absorb ambiguity. It resolves it, once, in the direction of whatever is most probable, and then it materializes that resolution across every file it touches. The generation step stopped being a filter and became an amplifier, and it amplifies whatever it was given, including the gaps. One ambiguous line in a specification becomes a dozen consistent, plausible, uniformly wrong code paths, in seconds, and they all look correct because they all agree with each other.

This is the real intensification. The cost curve was always steep, and it is now steep and fast. The window in which a human used to catch an upstream defect by “just writing the code” has closed, because the code writes itself before the human has time to notice the spec was vague. By the time anyone reads the output, the upstream defect has already been faithfully reproduced across the diff, and the reviewer is left arguing with the symptom instead of the cause.

Why Consequences Fan Out
#

The reason early stages outrank late stages is not only that they are cheaper to fix. It is that their defects multiply downstream while late-stage defects mostly do not.

A bug in code affects the code that contains it. A gap in the architecture affects every component built on top of it. A missing or wrong requirement affects every architecture that tries to satisfy it, every component that implements it, every test that verifies it. The earlier the stage, the larger the fan-out, because the larger the subtree of artifacts that descend from it.

This fan-out is why a specification defect is not just “a bug, but earlier.” It is a different category of problem, one whose blast radius grows with the distance from the source. A single ambiguity in a spec can be the common ancestor of a hundred production incidents, each of which looks like a separate bug to the engineer who responds to it, and each of which is, in fact, the same defect. Treat them as separate bugs and you will fix a hundred symptoms. Treat them as one and you fix the spec once.

Nancy Leveson reached the same conclusion from the study of accidents in Engineering a Safer World. Serious failures are rarely caused by a single component breaking. They are caused by flawed control structures upstream that set the components up to fail in concert, and the component failure is merely the place the upstream flaw became visible. The component is the symptom. The control structure is the cause. Fixing the component prevents that one incident, and fixing the control structure prevents the class. A pipeline stage is a control structure, and in software the earliest stages are the ones with the widest reach.

The Fix Belongs Upstream
#

Here is the operational consequence, and it is the whole argument in a single rule.

When a defect appears in code, there are two places to fix it. You can fix the code, which removes the symptom from this instance. Or you can fix the upstream artifact that produced the code, which removes the cause from every instance.

These look similar and are not. A code fix is a non-compounding fix. It patches one occurrence, leaves the source intact, and guarantees that the same defect will be regenerated the next time the pipeline runs against the same upstream artifact. A spec fix is a compounding fix. It changes the source, and every future generation inherits the correction automatically, for as long as the artifact exists.

This is the same compounding-versus-one-time distinction that makes specification outrank review, as Rethinking Code Review in the Age of LLMs argues: review catches a defect once, for the reviewer who happens to be reading, while a spec prevents the whole class from being generated. The principle does not stop at review. It runs the entire length of the pipeline. The defect you patch in code today is the defect the model writes again tomorrow from the same ambiguous spec, and the defect you fix in the spec today is the defect the model never writes again.

The discipline this implies is uncomfortable for teams that grew up triaging bugs at the bottom of the pipeline. It says that most “code bugs” in an AI-assisted codebase are not code bugs at all. They are specification bugs, or architecture bugs, that happened to surface in code. Treating them as code bugs, by fixing the code, is treating the symptom while leaving the disease in place to generate fresh symptoms next sprint.

A useful diagnostic comes straight from the five whys and the Toyota andon tradition: when the same class of bug appears more than once, stop the line, walk back up the pipeline asking why until you reach a process cause, and fix the process, not the product. Fixing the product gets you a working unit today. Fixing the process gets you a working line forever. The two investments have almost nothing in common, and teams that confuse them spend their lives re-fixing the same bug in new files.

What This Changes About Where You Spend Effort
#

If consequences amplify downstream and fixes compound upstream, then the allocation of engineering effort across the lifecycle is exactly inverted from where most teams spend it.

Most effort sits at the bottom of the pipeline. Writing code, reviewing code, fixing code, handling production incidents: these are the stages with the smallest blast radius and the least compounding return. They feel urgent because they are where the pain is visible, but they are also where an hour of effort buys the least durable improvement, because the upstream artifacts that produced the pain are still in place, still generating.

The high-leverage stages are at the top. Requirements, specification, and architecture are the stages whose defects fan out the widest and whose fixes compound the longest. They feel less urgent because the pain they cause has not happened yet, and when it does happen it will be blamed on the code, not on the spec that produced the code. The trap is that the bottom of the pipeline is loud and the top of the pipeline is quiet, and most teams optimize for the noise rather than for the leverage.

This is the same relocation The Shifting Bottleneck describes from a different angle. Once code writes itself, the bottleneck moves to verification, and the highest-leverage response is not to verify harder but to specify better, because specifying better reduces the volume of bad output that verification ever has to catch. The pipeline does not reward you for being good at a late stage. It rewards you for making the late stage unnecessary by being good at an earlier one.

What to Do Next
#

A few concrete moves follow, and each is an inversion of the default.

Treat every repeated bug class as an upstream defect. When the same kind of issue shows up a second or third time, stop fixing it in code. Walk back up the pipeline until you find the artifact that allowed it, and fix that. The rule is blunt and useful: fix at the source once, or fix at the symptom forever.

Invest disproportionately in specification. The spec is now the highest-leverage artifact in the pipeline, because it is the stage whose defects fan out the widest and whose fixes compound the longest. A team that under-invests here pays for it in every downstream stage, forever, at machine speed, and a team that over-invests here barely notices the downstream stages at all.

When you review, review the spec, not the code. Code review catches symptoms once, on the diff that happens to be in front of the reviewer. Spec review prevents classes of symptoms from being generated at all, across every future diff. An hour on the spec outranks an hour on the code, because the code is downstream of the spec and the spec constrains every diff that will ever be written from it.

Keep an upstream ledger on incidents. When something breaks in production, record not just the code-level cause but the pipeline stage where the defect was actually born. Over a quarter the pattern will show which upstream stages are leaking the most, and that is where investment pays back the most, because a single fix there retires a whole family of incidents.

And when the model produces bad output in the same module twice, do not write a longer prompt. Fix the module, or fix the spec that describes it, because as The Importance of Context When Interacting with LLMs argues, the upstream artifacts are the model’s context, and bad output is the truest signal you will ever get about where that context is incoherent. The model is showing you the leak. The right response is to fix the source of the bad output, not to keep correcting it by hand.

The Lifecycle Runs One Way
#

Defects ride the pipeline downstream and multiply as they go. Fixes can ride it upstream, and they multiply too, but in the opposite direction: one fix at the source prevents a thousand fixes at the symptom.

The team that understands this spends its best hours at the top of the pipeline, writing specifications and architectures that make most downstream defects impossible. The team that does not spends its best hours at the bottom, fixing code that the pipeline keeps regenerating from sources it never touches. Both teams are busy. Only one of them is getting durable work done. In an era when the downstream stages execute themselves, the only engineering that compounds is the engineering done at the top of the pipeline. Everything below it is maintenance.

See also
#

References
#


Read the Commits, Not the Manual: What OpenClaw's Git History Reveals About Scaling a Project

The most revealing document a software project writes is not its README, its CONTRIBUTING.md, or its architecture diagram. It is its commit history, because the commit history is the one artifact the project cannot rewrite after the fact. A process doc describes the project the maintainers wish they were running, and the commit log describes the project they are actually running, and the gap between the two is where every real lesson lives.

I spent time inside the git history of OpenClaw, a self-hosted personal AI assistant that talks to you across roughly two dozen messaging channels. It is an extreme case, and extreme cases are the easiest to read. In about seven months it accumulated over sixty-two thousand commits from more than three thousand contributors, which is somewhere close to two hundred and ninety commits a day, every day, since its first commit. That is a throughput at which most projects would have become impossible to follow, and it did not. The interesting question is why, and the commit history answers it more clearly than any roadmap could.

This article is a reading of that history, and the throughline is a single observation that the data makes impossible to miss. A project’s real architecture is not the dependency graph of its packages. It is the role structure of the people who land commits on it, and OpenClaw reveals that role structure with unusual clarity because it is large enough that the patterns survive any individual’s bad week.

The First Thing the Commits Show: Two Kinds of Maintainer
#

Run a contributor breakdown on any mature project and you will find that the top commit counts are dominated by one or two names. OpenClaw is no different. The founding maintainer, Peter Steinberger, is listed in CONTRIBUTING.md as “Benevolent Dictator,” and he accounts for well over half of all commits in the repository, roughly three times the next contributor. The second name down is Vincent Koc, listed as owning “Agents, Telemetry, Hooks, Security.”

You can read their titles and learn nothing, or you can read their commits and learn everything. The commit prefix and the merge behavior are the two signals that tell you what a maintainer actually does all day, and at OpenClaw they tell two completely different stories.

Roughly ninety-five percent of Peter Steinberger’s recent commits land straight on main with no pull request at all. His work spans every conventional-commit prefix in roughly equal measure: test:, fix:, docs:, ci:, refactor:, perf:. His scopes are the product itself, the agents, the gateway, the release machinery, the high-traffic channels. Read his last two hundred commits and you are watching someone build outward, exploring whatever he finds interesting that week, shipping releases, writing the docs for features he just invented, and rarely pausing to open a pull request against his own work.

Vincent Koc’s history is the mirror image. His recent work is almost sixty percent fix commits, and his scopes are a completely different surface: end-to-end tests, the QA lab, scripts, CI, and a scope that appears nowhere near the top of Peter’s list, deadcode. He opens pull requests. He uses the review process. Where Peter’s commits read as exploration, Vincent’s read as consolidation.

The contrast between Peter’s history and Vincent’s is the observation that triggered this article, and the temptation is to read it as a process failure on Peter’s part, the founder cutting corners, ignoring the queue, doing whatever he wants. That reading is wrong, and it misses the point. The two patterns are not the same job done at different levels of discipline. They are two different jobs, and a project of this size needs both of them to survive.

The Benevolent Dictator and the Steward
#

Strip the moral framing away and what you are looking at is a role separation so fundamental that every healthy long-lived project eventually rediscovers it, whether it documents the split or not.

One role is the visionary, the person whose job is to push the frontier outward. They build features that no user has asked for yet, because no user knows to ask for them. They write docs in the same commit as the code, because to them the doc is part of the feature. They commit straight to main because the bottleneck they are optimizing for is their own momentum, and stopping to open a pull request against themselves would be pure ceremony. The visionary does not read the issue tracker for direction. They read it, when they read it at all, for confirmation that the thing they already wanted to build has some demand. Their commits are the product roadmap, written in real time.

The other role is the steward, the person whose job is to keep the frontier from collapsing behind the visionary. They fix the bugs the new features introduced. They write the end-to-end tests that prove the feature actually works under load. They remove the dead code the visionary left behind when they pivoted. They route pull requests from the long tail of contributors through review, because someone has to, and the visionary will not. Their commits are almost entirely fix, test, refactor, chore, and they open pull requests not out of greater virtue but because their work touches shared, critical surface where a mistake costs everyone.

The visionary produces the entropy that makes the project grow, and the steward does the work that keeps the entropy from being fatal, and neither role is superior to the other. A project with only visionaries ships exciting broken things that no one can depend on. A project with only stewards stays clean and slowly dies, because no one is building the thing anyone wants to use next. OpenClaw has both, in volume, and that is the first and most important reason it has not collapsed under its own commit rate.

The practical lesson, if you run a project, is to name this split out loud instead of letting it generate resentment in silence. The most common failure mode is a steward who slowly concludes that the visionary is careless, and a visionary who slowly concludes that the steward is a brake on progress, when in fact each is doing exactly the job the other cannot. Peter’s direct-to-main habit is not a defect Vincent is tolerating. It is the signature of a role, and recognizing it as a role is what stops it from becoming a feud.

The Specialist Roles That Only Appear at Scale
#

Past the two primary roles, the commit history surfaces two more contributors whose work is so specialized it would be invisible in a smaller project, and whose existence is itself a signal of size. A project small enough for everyone to do a bit of everything has no specialists, and the appearance of specialists is the commit-history fingerprint of a project that has grown past the point where generalists can cover the surface.

The third most prolific contributor, going by Shakker, has roughly four thousand commits, and about two thirds of them are test:. There is almost no feature work in the history. This is a person whose entire contribution is the safety net, the test fixtures, the regression coverage that lets everyone else move fast without the product silently breaking. A visionary cannot do this work, because it requires the patience to write the hundredth test for a path the fortieth test already almost covered, and a steward is usually too busy handling urgent fixes to write tests in advance. The test author is a third role, and it is the role that converts the steward’s fixes from one-off patches into guarantees that do not have to be re-earned.

Further down the list, Tak Hoffman has a thousand-plus commits, and he owns a scope that appears in almost nobody else’s history: (regression). Of the hundred-plus commits in the repository tagged fix(regression):, almost all of them are his. Tak is a regression hunter, someone whose focus is not bugs in general but bugs in things that used to work, the specific class of defect that erodes user trust faster than any missing feature can build it. Regression hunting is a discipline of its own, because it requires holding a mental model of how the system used to behave and noticing when a change has quietly violated it, and it is the kind of work that only gets staffed deliberately once a project is large enough that the founding maintainer can no longer hold the whole behavior graph in their head.

The lesson is that the visionary-and-steward split is a starting frame, not a complete one. As a project grows, the roles keep subdividing, and each subdivision is a person whose commits tell you, by their narrowness, exactly what the project is now too large to handle with generalists. Read the contributors with unusual scope concentrations and you read the project’s growing pains written out in advance.

The Second Thing the Commits Show: The Real Architecture Is the Ownership Table
#

Three thousand contributors is a number at which coordination by conversation breaks down completely. You cannot have a meeting with three thousand people. You cannot maintain a shared mental model with three thousand people. The only way a project absorbs that many contributors without descending into a pull-request traffic jam is to partition the work so thoroughly that most contributors never need to talk to each other at all.

OpenClaw does this with an explicit ownership table, and it is the most underrated document in the repository. CONTRIBUTING.md lists roughly thirty maintainers, each with a named specialty: one owns Telegram, one owns the iOS app, one owns Memory, one owns the Discord subsystem, one owns Chinese channels and nothing else. The instruction to contributors is blunt: “Do not guess who to tag,” route through the ownership list, the label automation, and CODEOWNERS instead.

When the surface area of a project exceeds what any one person can hold in their head, the only scalable architecture is a partition, and the partition has to live in a file, not in tribal knowledge. The plugin layout reinforces this from the code side. There are around a hundred and forty-five extensions and only twenty-one core packages, and the project’s own vision document states the principle outright: core stays lean, capabilities ship as plugins, and the bar for adding an optional capability to core is “intentionally high.”

The plugin partition is the same insight as the role split, applied at the level of the codebase rather than the people. You cannot hold one hundred and forty-five channel adapters in your head, but you do not have to, because each one is owned by one person who only has to hold one in theirs. The partition is the architecture, and the ownership table is the partition made durable. A project that grows past a few active contributors without writing this table down is a project that will discover, painfully, that the absence of an ownership map is itself an architecture, an architecture in which the loudest reviewer owns everything by default.

The Third Thing the Commits Show: Every Rule Is a Scar on Reviewer Time
#

The contribution rules in OpenClaw are unusually specific, and a first-time reader will find some of them almost hostile. There is a hard cap of twenty open pull requests per author, enforced automatically, past which your pull requests are labeled and closed. Refactor-only pull requests are refused outright. Test-only or CI-only pull requests that chase a known main failure are refused outright. Pull requests over roughly five thousand changed lines are reviewed “only in exceptional circumstances.” One pull request must equal one issue or topic.

Taken in isolation, the rules read as pettiness. Read as a group they are responses to one specific, recurring problem, and the problem is always the same. Every one of these rules is a response to something that once drained reviewer attention without producing proportional value, because reviewer attention is the single scarcest, least-elastic resource a project at this scale has.

The visionary can always produce more commits. The contributor pool can always produce more pull requests. Neither of those can produce more maintainer-hours for review, and so the entire rule set is engineered to protect that one bottleneck. The twenty-pull-request cap exists because batch-opened pull requests impose review cost in proportion to their number, not their value. The ban on refactor-only work exists because a refactor that changes no behavior consumes review to confirm it changes no behavior, which is review spent proving a negative. The line limit exists because a five-thousand-line diff cannot actually be reviewed by a human, it can only be rubber-stamped, and rubber-stamping is the failure mode the gate is supposed to prevent.

The rule set is the theory of constraints applied to a volunteer workforce. When you cannot add capacity at the bottleneck, the only lever left is to choke the demand arriving at it, and you choke demand by making rules that reject the classes of work that waste the bottleneck’s time. A rule that reads as harsh to a contributor is almost always a rule that reads as triage to a maintainer who has been doing the job long enough to know which inputs are waste.

The Fourth Thing the Commits Show: They Dogfood the Future of Development
#

OpenClaw builds an AI agent, and it builds it with AI agents, and the commit history makes the second fact as visible as the first.

Bot accounts appear throughout the contributor list. The contribution guide treats AI-authored pull requests as first-class citizens, requiring only that they be marked, with a checklist that asks for the model, the prompt or session log, and a human confirmation that the code is understood. Codex review is not an experiment: it is described as the “current highest standard of AI review,” expected to run on every pull request and to be addressed by the author before a human reviewer is ever bothered.

The reason the dogfooding matters is not that it is futuristic. The project is a live, working answer to the question every team is now fumbling with, which is how to integrate generated code without being flooded by it. The OpenClaw answer is not to ban generated contributions and not to blindly trust them, but to treat their provenance as a required signal and to route that signal into both the review and the reviewer.

OpenClaw’s approach is the provenance argument I made, from the maintainer’s side, in Triaging Open Source Pull Requests: the one piece of information a reviewer most needs about a modern pull request is which model produced it and what prompt produced it, because that is the information that tells you which blind spots to check for. OpenClaw asks for exactly this information, up front, in the template, and it pairs the request with an automated review pass that can be calibrated against the disclosed model. That pairing, disclosure plus targeted automated review, is the most credible workflow I have seen for accepting generated code at volume, and it is sitting right there in a CONTRIBUTING.md that most projects have not yet caught up to.

How to Read a Project This Way Yourself
#

The method that produced these observations is generalizable, and it costs you nothing but a terminal. You do not need access to a project’s Slack, its planning board, or its maintainers’ intentions. You need its git history and three commands.

Start with the contributor breakdown, git shortlog -sne, and look at the ratio between the top name and everyone else. A project whose top contributor dwarfs the rest is a project whose direction is set by one person, and everything else is execution. A project whose top contributors are close in volume is a project run by committee, and its commits will read as negotiation rather than vision.

Then take the top two or three names and compare their conventional-commit prefixes, git log --author=... --format=%s, grouped by prefix. The ratio of fix to feat, the presence or absence of docs and test, the dominance of refactor or chore, these tell you who builds and who maintains, and they tell you in five minutes what would take a month of standups to learn. A maintainer whose commits are sixty percent fix is a steward. A maintainer whose commits span every prefix evenly is a visionary. The prefix distribution is a fingerprint of a role, and reading it is faster and more reliable than reading anyone’s job title.

Finally, count how many of each top contributor’s commits reference a pull request versus landing straight on main. This is the governance signal. A project where even the founder routes through pull requests is a project run by process. A project where one person lands on main freely and the rest use pull requests is a project that has, whether it admits it or not, a benevolent dictator and a steward, and the rest of the contribution rules will make sense once you see the split.

Run this analysis on your own project before you run it on anyone else’s. You may find that the role structure you assume you are running is not the one your commits describe, and the gap is the first thing worth fixing.

What to Do Next
#

If you maintain a project, take an hour and read your own commit history the way this article reads OpenClaw’s. Find your visionary and your steward, and if you do not have both, that is the single most important hiring or delegation decision in front of you. A project with no steward is slowly dying behind a pile of unmerged fixes and unread pull requests, and no amount of feature velocity will save it.

Write down your ownership table, explicitly, in a file, even if it is just three names today. The day you have thirty contributors is too late to invent the partition, because by then the loudest reviewer will have quietly become the owner of everything, and unwinding that is a political problem rather than a documentation one. The partition is cheap to write early and expensive to write late.

Audit your contribution rules as a set, not individually. Every rule that reads as harsh to a contributor should correspond to a specific class of work that once wasted your review time. Any rule you cannot trace back to a specific class of wasted review time is a rule that is probably driving contributors away without being worth its cost, and it is a candidate for deletion.

See also
#

  • The Codebase Gardener - the team-codebase argument that standards must be encoded where work passes through them, which is the lens this article uses to read OpenClaw’s rules as reviewer-time conservation
  • Triaging Open Source Pull Requests - the provenance argument this article extends: when the reviewer knows which model wrote a pull request, they know which blind spots to check, and OpenClaw’s disclosure template is a working implementation of it
  • The Merge Gate - the case for gating on the blast radius of a change rather than the existence of a pull request, which is the principle behind OpenClaw’s line limits and its refusal of refactor-only work
  • Rethinking Code Review in the Age of LLMs - why a machine-checked constraint outperforms a tired human scan, the premise behind treating Codex review as the default standard
  • Software Engineering Teams in the Age of AI - which friction is structural and which is waste, the distinction that explains why OpenClaw’s harsh rules are the former and not the latter

References
#

  • OpenClaw on GitHub - the repository whose commit history, CONTRIBUTING.md, and VISION.md are the primary sources for every observation in this article
  • Wikipedia, “Theory of Constraints” - Goldratt’s framing for why you protect the bottleneck rather than adding effort elsewhere, the basis for reading OpenClaw’s rules as reviewer-time conservation
  • Wikipedia, “Benevolent dictator for life” - the canonical name for the role OpenClaw’s commit history reveals in its top contributor, independent of any title

Team Maturity Explains the Friction, the Foundation Predicts the House of Cards

In the age of LLMs, the work that matters at your job is no longer adopting the tools. It is raising the velocity at which your team can ship features without turning the software it builds into a house of cards. When two teams hold the same tools and get wildly different outcomes, the first thing to study is the team itself, and Bruce Tuckman’s model of group maturity will explain a large share of the gap. But it will not explain all of it, because team maturity governs how easily a team absorbs a new practice, not whether the software that practice produces stays standing. Maturity is necessary and it is not sufficient, and most organizations are diagnosing only half the problem.

The Real Job Is Velocity Without Debt
#

Raw velocity stopped being interesting the year a model could draft a feature in an afternoon. Anyone can go fast now. The constraint that separates serious teams from reckless ones is sustainable velocity, the ability to ship quickly and also keep the system survivable as it grows.

The distinction is not new, and AI did not invent it. The DORA research program spent years measuring engineering organizations along two independent axes, throughput and stability, and its central finding was that you have to track both because they are not the same thing. Throughput is lead time and deployment frequency, how fast work gets out. Stability is change failure rate and time to restore, how often what you ship breaks and how long it takes to recover when it does. A team can score high on throughput and low on stability, and that team is not fast. It is a house of cards being shuffled quickly, and the cost arrives as rework, outages, and a codebase nobody is willing to touch.

LLMs increase the throughput axis for free. They do nothing for the stability axis unless your engineering system is built to hold them accountable. So the whole question of which teams ship effectively with LLMs collapses into a narrower one: which teams can absorb the throughput multiplier without their stability metrics collapsing? That is a property of the team and a property of the code, and the team part is only half of it.

Why Tuckman Explains So Much of the Adoption Gap
#

Before moving to the other reasons, it is worth being realistic about how much Tuckman’s stages of group development actually explain, because the answer is a lot.

A team in the performing stage adopts a new AI practice with low friction for reasons that are structural, not cultural. Its members have already negotiated how decisions get made, so “which code review workflow do we use now that the model writes most of the code?” gets resolved in one meeting instead of three. Its conventions are settled and shared, so when an engineer introduces a prompt template or a skill, the rest of the team can tell whether it fits the way they already work. It has the psychological safety that Project Aristotle identified as the strongest predictor of team effectiveness, which means an engineer can say “the model’s output is wrong here and I do not understand why” without that admission costing them status.

A team still in forming or storming has none of these assets, and so it pays the adoption tax on every change. As I argued in When Engineers Disagree on Best Practices, a team that has not yet built a repeatable process for resolving disagreements will relitigate the same practice debate over and over, and the debate is rarely about the practice. It is a proxy for unresolved questions about whose judgment the team trusts. LLM adoption surfaces a dozen of these questions at once, because it touches review, testing, specification, ownership, and onboarding simultaneously. A performing team processes all of that in the background. A storming team drowns in it.

So if your observation is “some teams picked up the new AI workflows easily and others fought about it for two quarters,” Tuckman is very likely your explanation. Team maturity is the dominant predictor of adoption friction, and adoption friction is the dominant predictor of whether a team even gets to the starting line.

What maturity does not predict is what happens after the team starts shipping.

The House of Cards Is Predicted by the Foundation
#

Here is the gap maturity cannot close. A mature, high-trust, psychologically safe team sitting on top of a brittle codebase with no tests and no specification discipline will still ship a house of cards. It will just do so with impressive cohesion, minimal interpersonal drama, and a strong retrospective culture. The team dynamics are good and the software is still wrong, because the things that decide whether generated code stays standing are properties of the engineering system, and those properties vary somewhat independently of how well the team gets along.

If you want to know why two mature teams with the same tools ship software of very different durability, look at the foundation. The factors below are not equal in importance. Two of them, verification and codebase health, decide whether the software stands up at all, and the other four only improve the quality of what gets built. No amount of strength in the four can compensate for weakness in the two, because the two are what keep the structure standing. For shipping without a house of cards, verification and codebase health outrank team maturity, and the rest exist to support them.

The two factors that outrank maturity
#

These are the structural ones. A team weak on either of them ships a house of cards regardless of how mature it is, and a team strong on both can survive even rough team dynamics. Everything else in the foundation eventually feeds into one of these two.

Verification is the throttle
#

Once code writes itself, the bottleneck moves to checking whether the code is correct, and that move is the central claim of The Shifting Bottleneck. Verification is where the stability axis lives, and it is why two teams with identical throughput can have radically different change failure rates.

The team with a fast, trustworthy test suite, a CI pipeline that catches real regressions, and a short feedback loop can let the model generate aggressively, because it can verify cheaply. Every generation is a hypothesis and the test suite is the experiment, and the cost of a wrong generation is seconds. The team that verifies by reading the diff, or by running the feature once in a staging environment, cannot afford to let the model run. It hits a ceiling where the human reviewer becomes the bottleneck, and either it slows down to stay safe or it speeds up and ships unverified code.

The difference between those two teams is the DORA stability axis measured in engineering practice. The team that ships safely with LLMs is usually not the team with the best prompters. It is the team with the best test suite and the fastest signal, because that team can convert the throughput multiplier into stable throughput instead of into rework. Investing in verification infrastructure is now the highest-return thing a team can do to raise its LLM shipping velocity, which is a counterintuitive claim only if you are still measuring velocity as lines produced rather than features landed without rollback.

The codebase is the model’s context
#

The other structural factor is that the LLM does not generate code in a vacuum. It generates code as a continuation of the context it is given, and the largest piece of context is the codebase itself. A clean, well-factored codebase with clear naming, consistent patterns, and a single way of doing each thing is excellent context, and the model faithfully reproduces its conventions. A tangled codebase with five competing styles, dead abstractions, and comments that contradict the code is terrible context, and the model faithfully extends the mess. As I argued in The Importance of Context When Interacting with LLMs, the context is the entire mechanism by which a frozen set of weights produces behavior relevant to your situation, and the codebase is the part of the context you control.

This is why the same model, the same prompt, and the same engineer produce different quality output on different codebases. The codebase is doing most of the work, and a codebase that is already a house of cards is a context that asks the model to build more cards. You cannot hand an LLM a weak codebase and get back a strong one; you get back more weak code. The teams shipping safely are, more often than they realize, the teams whose codebase was already safe to extend, and the LLM is merely making that pre-existing health visible at higher speed.

The factors that strengthen the foundation
#

The next four factors do not replace the first two. They decide how much wrong output the verification layer has to catch, and how high the ceiling on the best possible generation sits. A team that is strong here and weak on verification still ships a house of cards, just a slightly smaller one. A team that is weak here and strong on verification stays safe, but slowly, because its loop drowns in bad output it has to reject.

Specification discipline separates amplifiers from noise
#

An LLM is a multiplier on the quality of the instructions it receives, which means the teams that win are the ones that produce high-quality instructions at scale. This is specification, and it is the skill that Software Engineering Teams in the Age of AI names as the highest-leverage capability in the current era.

A team that writes a precise specification before it prompts, one that defines what done means, which invariants must hold, and which edge cases matter, gets an LLM that behaves like an effective pair programmer. A team that prompts first and specifies never gets a hallucination engine that produces plausible code solving the wrong problem, and the wrongness is often invisible until production. Specification is also where the human bottleneck genuinely lives now, because writing a precise spec is hard cognitive work that the model cannot do for you until you have done the thinking it depends on. Teams that institutionalize specification, through templates, through review of the spec before the implementation, through a skill that enforces the steps, pull away from teams that treat the prompt as the spec, and they pull away fast.

Conventions have to be written down to be inherited
#

A performing team has settled conventions, and that is exactly what makes the team mature. But settled conventions that live only inside the senior engineers’ heads are invisible to two important workers: the new hire, and the LLM. Neither of them received the osmosis.

The teams that ship consistent, safe output at scale are the ones that have externalized their conventions into a form the model actually reads. That means lint rules the CI enforces, architecture decision records that capture why a choice was made, contribution guides that name the patterns to reuse, and, most powerfully, skills that encode a team’s process as executable steps the agent follows on every run. A convention in a head is advice the model will ignore. A convention in a skill or a lint rule is a constraint the model has to satisfy.

This is the mechanism by which a mature team scales its maturity into the model. A storming team that somehow wrote its conventions down would get more out of the LLM than a performing team that left them tacit, which is a real inversion and a useful diagnostic. If your team is mature and your LLM output is still inconsistent, the conventions are probably in the wrong place. They are in people, and they need to be in files.

Review is a backstop, not the mechanism
#

The instinct when a tool speeds up code production is to use it to speed up code review, and on this point the instinct is closer to right than wrong, for a reason that is easy to miss.

Code review is a one-time signal. It catches what one reviewer notices, once, on the diff in front of them, while they happen to be alert. A specification prevents the whole class of issue from reaching implementation, and a test catches the same bug on every future run, for as long as the codebase exists. As Rethinking Code Review in the Age of LLMs argues, an hour spent improving the specification outranks an hour spent reviewing the output, because the specification compounds and the review does not. For the purpose of shipping without a house of cards, specification is the structural lever, and review is the non-compounding backstop behind it.

The backstop still has a job, but it is narrower than the one review used to claim. With generated code the reviewer is the only brain in the loop, so a light, intent-focused check still catches the occasional wrong assumption before it ships. What it does not do is scale. If the model produces ten changes a day, ten hours of human review is not a process that survives, and the right response to a repeated class of review comment is to encode it as an automated gate so it never depends on a human noticing again. The teams that ship safely let the model handle style, keep a thin intent check as the backstop, and spend the freed review hours writing better specifications. The teams that ship a house of cards inverted this, keeping review heavy while starving the specification that actually prevents the cards.

Domain depth and the discipline to build less
#

Both of the following are judgments the model cannot make for you: what the software should do, and whether it should exist.

On the first judgment, the model produces code that is technically correct and strategically wrong, faster than ever, when nobody on the team deeply understands the business context. Deciding whether a feature should exist, and what form it should take, is the part of the pipeline AI cannot do, and it is the bottleneck the throughput multiplier pushes you into, exactly as the shifting bottleneck predicts. A team with deep domain ownership extends its system coherently. A team spread thin across too many concerns generates five services where one would do, and each of them is a card.

On the second judgment, cheap implementation makes overbuilding the default temptation. Every generated feature is surface area for bugs, cognitive load, and future constraints, and the cost of maintaining a feature never approached zero the way the cost of writing it did. The team with the discipline to say “we do not need this, ship the smaller thing” survives longer than the team that ships everything the model can draft, and that discipline is a product judgment that maturity does not produce on its own. It comes from somewhere else, usually from someone in the room who has seen the cost of feature bloat before and is willing to push back against it.

How Maturity and Foundation Interact
#

The fair synthesis is that these two layers reinforce each other, and the most effective teams are strong on both, but they fail in characteristically different ways.

A performing team on a clean foundation with strong tests and written conventions is the team that wins this era. It absorbs new AI practices without friction, and when it ships, the foundation catches what the model gets wrong. A performing team on a brittle foundation fails in a way it cannot see, because the team dynamics are good and so nobody is arguing, and the stability metrics degrade quietly until a production incident makes them visible. A storming team on a clean foundation still wastes most of its energy on the wrong fights, but its code tends to survive the fights because the foundation holds. A storming team on a brittle foundation fails loudly and fast, which is at least easy to diagnose.

The trap is to read every symptom as the layer you already know how to fix. Engineering management tends to diagnose everything as team dynamics, because that is the toolkit it has, and so it sends a brittle-foundation team to a retrospective when what it needs is a test suite. Engineering teams tend to diagnose everything as tooling, because that is the toolkit they have, and so they adopt a new model when what they need is a written convention. The binding constraint is usually the layer you are not looking at, and maturity is very good at hiding problems in the foundation because a mature team does not complain about them until they break.

What to Do Next
#

If you lead a team and want to know whether you are shipping features or shipping cards, a few concrete moves separate the diagnosis from the guesswork.

Measure both DORA axes, not just throughput. If your deployment frequency is rising and your change failure rate or time to restore is rising with it, you are not getting faster. You are getting more volatile, and the LLM is the reason. The stability metrics are the house-of-cards indicator, and they are free to collect.

Treat the codebase as context and pay down the part the model keeps getting wrong. If the LLM consistently produces bad output in one module, that module is bad context, and the fix is to refactor the module, not to write a longer prompt. The model is telling you where your code is incoherent, because incoherent code is exactly what it reproduces worst.

Write your conventions down somewhere the model reads them. A skill, a contribution guide, a lint rule, an architecture decision record, anything that moves a standard out of a head and into the execution path. The test is whether a new engineer and a fresh agent both produce work that matches the team’s patterns on day one without being told.

Keep a thin, intent-level review as a backstop and let the model own style. If your review comments are still about formatting, you are spending human attention on the part the model already fixed. Reallocate those hours into specification, which is the lever that compounds.

Write the specification before the prompt, every time. The spec is the highest-leverage artifact in the pipeline now, and the team that treats it as optional is the team whose LLM output drifts toward plausible-and-wrong.

The Team That Wins
#

The teams that win this era are easy to misread. They look like the most mature teams, and they often are mature, but the maturity is doing a specific job. It is letting them adopt new practices without bleeding energy, so that they can spend that energy on the foundation that actually decides whether the software stands up.

Maturity is how you remove the friction of getting started. The codebase, the tests, the specifications, the written conventions, and the intent-level review are how you keep the result from collapsing under its own weight. Study your teams, because Tuckman will tell you a lot. Then study the code they are standing on, because that is what determines whether the velocity they have earned is velocity they get to keep.

See also
#

References
#


The Pull Request Queue Outgrew You: A Triage Layer for Open Source Maintainers

Open source always had a queue problem. For most of its history the threat was volume: more pull requests than a maintainer could read, arriving faster than one unpaid person could clear. The pull request queue scales with the project’s popularity, and a single maintainer’s attention does not scale with anything at all.

That is still true, and it is no longer the worst of it. The character of the queue changed. More than one in five code reviews on GitHub now involve an agent, and Copilot’s automated review alone has run more than sixty million times, growing tenfold in under a year, so the machine-generated pull request is no longer a fringe of the queue. It is becoming the norm, and a machine-generated pull request is a different kind of problem than a human one. It looks correct, because plausibility is exactly what a language model optimizes for, and it may be subtly, uniformly wrong in ways that read as confident and clean. There is usually no author who thought about each line, so there is no intent for you to leverage as context, only output you have to verify from scratch. And almost never does the contributor tell you which model produced the code, what prompt generated it, or whether a human ever read it before it landed in your queue. The flood is not just bigger now. It is full of plausible code with no provenance, and plausible, unprovenanced code is the hardest thing in the world to triage by reading it.

The instinct of a responsible maintainer is to read every pull request, carefully, and reply thoughtfully. That instinct is exactly what kills the project. Every half-hour spent reverse-engineering an AI-generated PR that looks reasonable until the third function is a half-hour not spent on the architectural change that keeps the library alive. The queue grows while you sleep, and while you are polite, and while you are giving a stranger’s model the benefit of the doubt.

You cannot review your way out of this, for the same reason a team engineer cannot: per-unit review scales linearly with your hours, and the entropy is produced faster than you can read it. The difference is that on a team you can hire. In open source, you are usually alone, unpaid, and tired, and the code you are being asked to vet no longer carries the reasoning of the person who submitted it. The only way out is to stop reviewing everything and start triaging everything, so that your scarce attention lands only on the pull requests that deserve it.

Triage Before Review
#

Review answers the question, “is this code correct?” Triage answers a cheaper question that comes first: “does this pull request deserve my attention at all, and if so, how much?”

Most maintainers fuse the two. They open a pull request, start reading the diff, and only then discover that it is stale, that it conflicts with main, that it has no tests, that it touches a file nobody asked it to touch, or that it is the fourth duplicate of a request they already declined. Every one of those discoveries was free to make before reading a single line of code, and making them up front is the entire difference between a queue you manage and a queue that manages you.

A triage layer is the set of automated signals that answer the cheap questions before you ever open the diff. Does it still apply? Does it still merge? Is it small or sprawling? Is it risky or routine? Who is it from? Does it match the conventions the project already requires? Each of these is a machine-checkable property, and a property a machine can check is attention you never have to spend again. This is the same move The Codebase Gardener makes for a team codebase: encode the standard where every change is forced to pass through it, instead of carrying it in your head as a review habit.

The goal of the triage layer is not to merge everything automatically. It is to make the queue sortable, so that when you sit down with your limited hour, you are looking at the five pull requests that matter, ranked, instead of the fifty that arrived in the order they happened to come in.

Plausibility Is the Danger, Provenance Is the Missing Signal
#

Understanding why the modern queue is dangerous is what defines the triage layer, because AI-generated code breaks the assumptions review used to rest on.

When a human wrote the pull request, you and the author shared a mental model. You could trust that the choices in the diff were deliberate, even imperfect ones, and a gap between your expectation and the code was an interesting signal, because it represented two human understandings of the same problem meeting. When a model wrote the code, there is no shared mental model, and there is no author who deliberated. The code is the output of a pattern-matching process, internally coherent, consistent with nothing around it, and wrong about the domain in ways that look exactly like correctness. This is the argument from Rethinking Code Review in the Age of LLMs, and it lands hardest in open source, where the reviewer and the “author” have never spoken.

What makes this crisis specific is the provenance gap. Contributors almost never disclose that the code is generated, let alone which model generated it, what prompt produced it, or whether a human checked the output before opening the pull request. Without provenance, you cannot assess risk. A fifty-line patch from a contributor who tested it by hand and a fifty-line patch a model hallucinated in three seconds look identical in the diff, and the diff is all you have. Plausible code with no origin story is the default input now, and it forces a worst-case assumption on every pull request: treat it as unverified until something proves otherwise.

The 2026 data shows how invisible this is by default. A census of 180 million repositories found that the obvious signal, a bot account, recovers only about three percent of the commits AI coding agents actually produced, so the overwhelming majority of machine-generated code reaches you with no detectable fingerprint. And the studies that watched what reviewers did with it found the same pattern: agent-generated pull requests carry more redundancy and technical debt than human ones, yet reviewers express more positive sentiment toward them, and the majority of AI-coauthored pull requests merge with no explicit human review at all. Plausibility is doing exactly the work of hiding the problem.

The implication for triage is concrete. First, the durable defense against plausible code is not a sharper opinion but a machine-checkable gate, because opinion-based review loses against code that was designed to look right. Tests, static analysis, type checking, reproducible builds: these operate on what the code does, not on how it reads, and they do not get fooled by confident prose. Second, the absence of provenance is itself a routing signal. A large, high-churn, undocumented pull request from an unknown contributor should default to high-risk, not because the contributor is malicious but because you have no evidence to assign it anything lower. Third, the one piece of information that would most improve your triage, which model and what prompt, is the one nobody is giving you, which means the cheapest high-leverage intervention available is to start asking for it.

Let Automation Carry the Logistics
#

The first tier of triage is pure logistics, and all of it is solved. You should not be tracking any of this by hand, and in 2026 you increasingly do not even have to build it yourself. The most consequential shift is that GitHub started shipping these gates at the platform level, because the flood crossed a threshold unpaid maintainers could not hold: per-user caps on open pull requests, pull-request archiving, and “smarter bypass” signals based on account age and merge history. The stated rationale is the one this article rests on: the cost to create a change has fallen below the cost to review it. When the host carries the load, your job narrows to the gates the platform cannot generalize.

Mark and close the stale, on a clock that forces a decision. A pull request that has had no activity for twenty-eight days is not waiting for you. A stale pull request drags down the whole queue, because a queue full of stale PRs signals to new contributors that the project is unmaintained. actions/stale marks a pull request stale after twenty-eight days, posts a warning, and closes it seven days later if the contributor does not respond. Twenty-eight is also the ceiling on a healthy open pull request, not just the stale timer. If a PR has been open more than twenty-eight days and is not merged, the right answer is almost never “keep waiting,” it is one of two things: break it into smaller pieces that can each land on their own, or reject it. A large PR that lingers is usually a PR that was too big to review in the first place, not a PR that is waiting for a reply. This is not cruelty. Letting a contributor’s work sit unread for a year is cruelty. A fast, automatic close with a clear “reopen if you are still interested” is a kindness, and it is a kindness that costs you nothing.

Surface the conflicting. A pull request that no longer merges cleanly is a pull request that is wasting your attention, because until the contributor rebases, your review is provisional. eps1lon/actions-label-merge-conflict adds a merge-conflict label the moment a PR falls behind main, and removes it the moment it merges again. Now you can filter label:-merge-conflict and only review work that is actually ready. The contributor also gets a clear, automated nudge that rebase is needed, without you having to be the one to say it.

Label by size. The blast radius of a change is the single best predictor of how much attention it deserves, a point I made in The Merge Gate: a README typo and a schema migration are both pull requests, and they do not need the same gate. A size action tags every PR with size/S through size/XL based on diffstat. Small changes become candidates for fast-track; large ones become candidates for “please split this.”

Label by area. actions/labeler tags a pull request based on which files it touches, so you can route area/ci, area/docs, area/security to the right context, or skip the areas you are not the expert in.

Flag the first-timers. Label first-time contributors explicitly. Not so you can be suspicious of them, but so you can be generous with them, because a good first review is how a first-time contributor becomes a second-time contributor, and a second-time contributor is how a project outlives its original maintainer.

Enforce the conventions you already require. If your project requires a linked issue, a semantic title, a signed commit, a test for every new function, enforce each one with a check that runs on open. amannn/action-semantic-pull-request is one example, but the specific tool matters less than the principle: anything you find yourself typing in review comments repeatedly belongs in a check that fails the build. A review comment is a standard you enforce only when you are awake. A failing check is a standard that runs forever.

Gate at the trust boundary, before the diff. The bluntest triage signal is whether you have any reason to trust the contributor at all, and in 2026 the canonical implementation of that idea is mitchellh/vouch, built for the Ghostty terminal against a wave of AI slop. It auto-closes pull requests from unvouched contributors and routes them through a vouching issue, so the queue you actually read is the queue from people who have earned a hearing. It is a strong filter, and a truthful one to use carefully: the cost is friction for legitimate newcomers, which is why the vouching path has to be a real door, not a wall.

Each of these is a small automation, and none of them review code. Together they collapse the queue from “everything that arrived” to “everything that is ready, relevant, and sized.” That is most of the battle, and it cost you zero hours of reading diffs.

Demand Provenance
#

The single most valuable triage signal is the one the current ecosystem refuses to provide, which means the maintainer has to require it.

Add two fields to your pull request template, and make them hard to skip. Was this change generated or significantly assisted by an AI tool? If so, which model, and what was the prompt or task description? A checkbox and a free-text line are enough. You do not need a policy on whether AI contributions are welcome; you need the data to triage them on their actual risk rather than on a guess.

This is no longer hypothetical. In 2026, rust-lang wired an AI policy into its contributing guide and pull request template, and it is not alone: scipy asks for the model name, qemu requires code provenance, Ghostty ships an AI_POLICY file, and the Linux kernel has long held the submitter responsible for attesting to AI-generated code. The convention is fragmenting into a field of per-project rules, which is messy, but the direction is clear, and the closest thing to a shared format, declare-ai’s provenance file, is emerging for exactly this gap. The platform will not hand you this signal for free. Everything GitHub has shipped for maintainers, per-user caps, archiving, smarter bypass signals, operates on volume and account history, and none of it tells you which pull requests a model wrote. If you want provenance, you have to ask for it in the template.

Label from the answer. human-authored, ai-assisted, ai-generated, and a tag for the model when it is disclosed. Now provenance becomes a filter and a routing input instead of a mystery. A human-authored patch from a known contributor with passing tests can travel the fast lane. An ai-generated patch with no model disclosed and no linked issue starts one gate further back, by default, because it carries the provenance risk this era is defined by.

Be explicit that disclosure is not a penalty. The penalty is discovery, when you eventually realize a PR was generated and the contributor hid it, because at that point the trust that makes open source work is gone and the PR is closed on principle. Disclosure is what lets a generated contribution compete for your attention on its merits. Concealment is what makes every generated contribution read as an attempt to slip something past you.

One caution, because the obvious next step is to reach for cryptographic attestation: signed provenance is not the same as trustworthy provenance. In 2026, cryptographically valid supply-chain attestations were produced for malicious packages, which means a signature confirms a chain of custody, not that the code is safe. Demand disclosure, but verify the code on its own terms, not on the strength of the attestation alone.

A maintainer cannot triage what they cannot see, and in a queue full of plausible code, the origin of the code is the first thing they need to see.

Let the LLM Do the First Pass
#

Once the logistics are handled, the remaining question is the one automation traditionally could not answer: is the code itself any good. That used to require a human, because reading a diff and reasoning about its consequences was exactly the task machines could not do. It is not anymore. An LLM will not review a pull request as well as you would, but it will review it in seconds, on every pull request, at three in the morning, and it will produce a structured signal you can sort and filter on. That is a different value than correctness, and for triage it is the value that matters.

The 2026 evidence is now strong enough to separate the hype from the result. On the hype side, independent benchmarks are blunt about the ceiling: across eight frontier models, reviewers catch only fifteen to thirty-one percent of the issues humans flag, and adding more context makes them worse, not better, while the first independent cross-vendor ranking puts the best tool at an F1 near fifty-one. An LLM review is a noisy signal, and treating it as a verdict is the mistake. On the result side, the largest production deployment of the year ran a hundred and thirty thousand review passes across five thousand repositories, and engineers reached for the human “break glass” override on six tenths of one percent of merge requests. That number is the point: the system ran unattended on the easy tier not because the model was a great reviewer, but because it was a great sorter, tiering by risk and handing a coordinator a structured finding to deduplicate and rank.

Run an LLM review on every pull request when it opens and on every push that updates it. Give it your evaluation criteria, explicitly, the same checklist you would walk through mentally if you opened the diff yourself. Does it add a new dependency? Does it change a public interface? Does it touch security-sensitive code paths? Does it introduce backward/forward-incompatible behavior? Are there tests for the new behavior? Does it match the naming and structural conventions of the surrounding code?

Ask for the output as structured data, not prose. A risk score and a confidence score, say on a one-to-five scale, a one-line summary, and a short list of specific findings. Then parse those fields and turn them into labels. risk:low, risk:medium, risk:high. confidence:high, confidence:low. needs-human-review when the model is unsure or when the risk is high. auto-merge-candidate when the risk is low, the confidence is high, the size is small, the tests pass, and the contributor is trusted.

Now your queue is sorted by signal instead of by arrival time. The pull requests that are low-risk and high-confidence can be merged on green, or queued for a single glance, because the LLM has already done the scanning work you would have done anyway. The pull requests that are high-risk, or where the model is uncertain, rise to the top of your attention with the findings already attached. You are no longer choosing what to read. You are confirming or rejecting a hypothesis the triage layer has already formed.

Wire those scores back into the logistics layer, so a pull request that fails the review does not just sit and wait for you. When confidence drops below three or risk climbs above three, post a comment that tells the author the specific findings they need to address, and let the stale action treat that as the notice that starts the closing clock. The contributor gets a concrete path to merge instead of silence, and if they do not take it the pull request closes itself, decided by the standard you encoded rather than by your mood on a given Thursday.

A few cautions, because this is the part people get wrong.

The LLM review is advisory, not authoritative. It hallucinates, it misses subtle bugs, and it is confidently wrong in exactly the way that makes you want to trust it. Never wire it to merge on its own verdict for anything that crosses a trust boundary, changes a public contract, or is hard to undo. Use it to route attention, not to replace it, and reserve the replaced attention for the small, reversible, low-risk changes where being wrong is cheap to fix. This is the same risk-based gating The Merge Gate argues for: the unit of gating is the blast radius of the change, not the existence of the pull request.

The deepest caution is specific to this era, and you have to internalize it before trusting any automated score. When an LLM reviews code that an LLM wrote, the reviewer shares the generator’s blind spots. Both are statistical models trained on overlapping corpora, and a mistake plausible enough for one model to make is often plausible enough for the other to overlook. Two models agreeing that “this looks fine” is a weaker signal than either model issuing that verdict alone, and if the reviewer and the generator come from the same model family the agreement proves almost nothing.

In 2026 this stopped being a conjecture. Recursive self-training studies show that an AI reviewer gating its own output collapses into a rubber-stamp regime, where acceptance scores rise while correctness falls, and that only model-independent checks, compilation, types, tests, slow the collapse without stopping it. The one direct measurement of the effect found that heterogeneous pairs, a Claude reviewer over Codex output, flag a defect sixty-nine percent of the time, where homogeneous pairs flag it only fifty-three percent of the time. Same-family agreement is measurably weaker than cross-family agreement, which is the empirical form of the warning above.

This is why provenance matters at the review layer as well: feed the disclosed model and prompt into the reviewer’s context so it can target the failure modes that model is known for, rather than re-reading the diff through the same lens that produced it. And it is why, for ai-generated pull requests, you must discount the confidence score and default toward needs-human-review unless the change is independently verified by something that does not share the blind spot: a passing test, a type checker, a reproducible build, a specification the code is checked against. The LLM review is one signal in the triage layer, never the only one, and against generated code its job is to surface hypotheses for a human or a gate to confirm, not to pronounce the code correct.

Calibrate by reviewing the reviewer. For your first month, read the LLM’s review on every pull request you also review yourself, and keep a tally of where it was right, where it was wrong, and where it missed something you caught. That tally tells you which criteria to strengthen in the prompt and which labels to distrust. An uncalibrated LLM gate is a liability. A calibrated one is a second pair of eyes that never gets tired, and that gets more accurate every time you adjust the criteria.

Post the rationale, not just the label. Have the action leave the summary and findings as a comment on the pull request. The contributor sees what was flagged, the maintainer sees why a label was applied, and the verdict is auditable rather than a black box. Transparency is what keeps an automated review from feeling like a gatekeeping robot, and it is what lets a contributor fix the problem before you ever have to look.

Route by Risk, Not by Arrival
#

Once the triage layer is producing labels, the routing writes itself, and it should match the risk profile of each change rather than the order it was submitted. The tiering is no longer theoretical: the production system cited above classifies every change into trivial, lite, or full tiers and spends twenty cents of review on a typo fix where it spends a dollar sixty-eight on a sprawling one, because the gate a change deserves is a function of its blast radius, not its existence.

Low risk, high confidence, small, passing tests: auto-merge on green, or batch them into a single weekly pass where you glance and click. High risk, or low confidence, or large, or crossing a security boundary: hold for human review, and review those first. AI-generated with no model disclosed, or no linked issue, or no tests: default to the human queue until a test or a specification proves it, regardless of how small it looks, because small and plausible is exactly the profile of a subtle bug. First-time contributor: prioritize the response, because the speed of your first reply decides whether they come back. Conflicting: invisible until rebased. Stale: closed.

Within the human-review queue, attack the oldest first. A pull request that has waited the longest is the one closest to going stale, and clearing it, by merging or by closing, is what keeps the queue from accumulating a tail that nobody will ever reach, so weight your attention toward age, not toward whatever happened to land on top today.

This is the open source version of the argument from The Merge Gate: treating every pull request as needing the same gate is a failure to think about risk, and most pull requests do not need a human at all. The maintainer who wins is not the one who reads the most diffs. The maintainer who wins is the one whose queue has been pre-sorted so that the diffs they do read are the only ones that ever needed a human.

The Contributor Relationship Is the Hidden Triage
#

There is a layer underneath all of this, and it is the one maintainers most often neglect, because it is not technical. Most of the pain of an overflowing queue is not the code. It is the guilt of unanswered contributors, the dread of opening the tab, and the slow resentment of work that is supposed to be voluntary but has started to feel like a debt.

Automation is part of the answer, but so is setting expectations, because a contributor who knows what to expect does not require a personal reply to stay patient.

Write a CONTRIBUTING.md that says what you will and will not accept, what a good pull request looks like, and how long response takes. Use a pull request template that asks for the linked issue, the motivation, and the test. Publish a response-time norm, even a truthful one: “I review pull requests on Thursdays.” State it, link it in every template, and let the automation reinforce it. Predictability is a contribution, and a maintainer who responds every Thursday is more sustainable than one who responds in a burst and then disappears for three months.

The economics underneath this are shifting, slowly. The clearest 2026 voice on maintainer sustainability argues that the polite channels, sponsorship and pledge drives, have failed, and that maintainers should take open source work on company time rather than donate their evenings, because attention donated after hours is attention that does not scale. The funding is real but thin: sovereign and industry programs disbursed millions to individual projects this year, with a sovereign fund investing over a million euros in a single project and the open source pledge setting a two-thousand-dollar-per-engineer floor, yet no 2026 survey has measured whether maintainer burnout actually fell. Treat the automation and the expectations as the structure that carries the weight, and the funding as the still-insufficient subsidy.

And learn to close fast. A fast, clear “no, and here is why” is a gift. It respects the contributor’s time, it keeps the queue fair, and it is almost always kinder than a silence that stretches into a year. The maintainer’s fear of seeming ungrateful is what swells the queue past recoverability. A no is not ungrateful. A no is an answer, and an answer is all a contributor is waiting for.

What to Do Next
#

You do not need to build the whole layer at once, and you should not try. Pick the single thing that is costing you the most attention right now and automate that one.

Add actions/stale and let it start closing the pull requests you were never going to get to. Add eps1lon/actions-label-merge-conflict and stop looking at diffs that are not ready to merge. Add a size labeler and a path-based labeler and make the queue sortable. Write the CONTRIBUTING.md you have been meaning to write, and add the two provenance fields, AI-assisted yes or no, and which model, to the pull request template, so every contribution arrives with the one piece of context this era hides by default. If the flood is mostly from contributors you have no reason to trust, add a trust gate like vouch before any of the rest, because closing unvouched pull requests up front is the single largest reduction in queue size available to you.

Then, and only then, wire in the LLM first-pass review. Start it in shadow mode, posting its summary as a comment without applying any labels, and read along with it for a month. When you trust its risk and confidence calls, turn the labels on. When you trust the labels, let the lowest-risk, highest-confidence, smallest changes merge on green. Each step is a slice of attention you stop spending by hand and start spending on the pull requests that actually need a human.

A sustainable open source project is not one where the maintainer reads everything. It is one where the maintainer has built a triage layer good enough that almost nothing needs to reach them unread, and what does reach them is exactly what was worth their time. Build that, one automation at a time, and the queue stops being the thing that owns you.

See also
#

  • The Codebase Gardener - the team-codebase version of the same argument: encode the standard where work is forced to pass through it, instead of carrying it as a per-PR review habit
  • The Merge Gate - the case for gating on the blast radius of the change rather than on the existence of a pull request, which is the principle behind risk-based triage routing
  • Rethinking Code Review in the Age of LLMs - why an automated first pass plus a precise specification outperforms a tired human scanning a diff, the premise the LLM review layer stands on
  • Defects Flow Downstream, Fixes Must Flow Upstream - why repeated review comments signal a missing check rather than a missing reviewer, the root of “encode it, do not retype it”

References
#


Learn the Foundation, Not the Syntax: Why Low-Level Languages Still Matter When the Machine Writes the Code

The question gets asked as a binary choice: either drill new developers on low-level languages until they can write a kernel from memory, or accept that writing code is finished and retrain everyone into prompt-wielding product managers. It is a false dichotomy, and both branches are wrong for the same reason. They both confuse the surface of programming with the thing programming was always meant to teach, and that thing is now the only part AI cannot do for you.

Two Errors, Shared Confusion
#

The “teach them everything” camp treats low-level fluency as a production skill. It points at manual memory management, pointer arithmetic, and hand-rolled data structures as requirements for entering the profession, and it is right that these were once essential. It is wrong that they still are, as production. Writing C by hand stopped being the bottleneck the year a model could write it, read it, and port it faster than a careful senior could, and the market has already priced that in.

The “writing code is over” camp takes the same observation and extends it too far. If production is automated, the argument goes, the developer’s job becomes specification and orchestration, and the foundation the code runs on is somebody else’s problem, probably the machine’s. This is the AI-maxxing error applied to education, and it is the more dangerous of the two, because it feels like foresight while quietly removing the one capability that becomes scarcer and more valuable exactly as production gets cheap: the mental model of how the system actually behaves.

Both camps make the same mistake the resistor and the maximalist make in AI-Maxxing and Resistance Are the Same Mistake: they argue about how much low-level to use instead of asking what low-level is for. The answer to that question dissolves the debate.

What Low-Level Actually Teaches, and Why It Compounds
#

Strip away the syntax drills and the “implement linked lists in C” hazing, and a low-level language is a teaching apparatus for a small number of durable mental models. None of them are about the language. They are about the machine the language sits on top of, and they are exactly the models that become structural once you can no longer trust the code you are reading.

A model of execution. What lives in memory, what gets allocated where, what a call frame is, what happens when a function returns. This is not trivia. It is the difference between an engineer who can read a stack trace and one who can only read an error message, and the generated code that breaks in 2026 breaks in ways that only the first engineer can diagnose.

A model of cost. Big-O is taught in school and forgotten because it is inert until you have felt a cache miss, an allocation storm, or an N-plus-one query at the boundary between the ORM and the database. Low-level work is the cheapest known way to experience that cost directly, and once experienced it transfers to every higher language you will ever use. When the model produces plausible code that is also quietly quadratic across a network boundary, the person with a cost model catches it and the person without ships it.

A model of failure. Low-level code fails loudly: a segfault, a leak, a data race, a corrupted pointer. The cause is concrete and the lesson sticks. High-level and generated code fails softly, at the seams between abstractions, and the softness is the hazard, because soft failures train nothing and accumulate until they become outages. The engineer who learned on hard failures can debug the soft ones. The reverse is not true.

And, most importantly, a model of where the abstractions leak. Every stack you will ever work on is a tower of abstractions, and every one of them leaks under stress: the ORM leaks into SQL, the garbage collector leaks into latency, the container leaks into the kernel, the model’s confidence leaks into a hallucinated API call. When a leak surfaces in production, the person who can see through the abstraction to the layer underneath is the person who fixes it. Everyone else files a ticket and waits.

These four models are not production skills. They are not even, strictly, low-level skills. They are durable skills, in the sense Keeping Up With AI Is a Losing Strategy draws between the ephemeral and the durable: they do not decay across model generations, and they make every other thing you do, including supervising a model, more effective. That is the entire case for low-level in one sentence: it is the most efficient known way to build the models that do not depreciate.

Why “Writing Code Is Over” Is the Dangerous Half
#

Here is the asymmetry that settles which error matters more.

Forgetting low-level syntax is a recoverable error. The developer who never memorized the C calling conventions can look them up, or ask the model, the day they need them, and the cost is a few minutes.

Losing the mental model is not recoverable in the moment you need it. When the generated code is failing in production at three in the morning, there is no time to develop an intuition for memory layout, and the model that wrote the code is the same model confidently misdiagnosing it. You can build a mental model with an LLM as a tutor, over time, the same way you can build one with a good textbook or a patient colleague; the tool is not the obstacle, the hours of deliberate study are. What you cannot do is prompt one into existence under time pressure, and using the model to debug its own output already presupposes the very model it would take weeks to grow.

This is the shifting bottleneck in its clearest form. Production was the bottom of the stack, and automating it moved the constraint up to verification, and verification is precisely the layer that demands the foundation knowledge the “code is over” camp wants to skip. The preparation that says “we will not need this because writing is automated” is the preparation that makes you unable to do the job writing’s automation created. You are optimizing away the exact layer the bottleneck landed on.

There is a near-term counter-argument worth taking seriously: that verification gets automated too, and then specification, and so on up the stack. Even granting that, the same framework says the bottleneck just moves to deciding what to build and whether what was built is correct, which still requires understanding systems deeply. I cannot find a version of this future in which understanding the foundation stops compounding, only versions in which the surface syntax stops mattering. Those are different claims, and the debate quietly collapses them into one.

The Onboarding Hole the Tools Opened
#

There is a structural reason this question is urgent now, and it is not philosophical. For most of the profession, a developer built their mental model of systems the only way the model can be built: by struggling with code that broke, reading core dumps, profiling slow paths, and fixing real failures under real pressure, repeatedly, for years. The struggle was the curriculum, and it was free, because it was simply the job.

The tools have quietly removed the struggle, and with it, the curriculum. An engineer who starts today can ship a feature without ever reading the code the tool wrote, without ever opening a profiler, without ever needing to understand why the first version was slow, because the tool never produced a slow first version for them to fix. The onboarding path that used to build that underlying mental model now bypasses it, and the onboarding paradox in Software Engineering Teams in the Age of AI is the downstream symptom: juniors ship faster and understand less, and the understanding gap is invisible until something breaks.

So the question is not whether to teach low-level. It is whether to teach it deliberately, because the accidental curriculum that used to teach it for free has been automated away. A generation that learns to prompt before it learns how a machine actually executes will be fluent at the surface and hollow at the foundation, and the hollowness will only become visible at the moment it becomes expensive, in production, at three in the morning, with no model able to help.

The Synthesis: Read the Foundation, Don’t Write It
#

The resolution is not a midpoint between the two camps. It is a different axis entirely.

Stop teaching new developers to produce low-level code as if they would ship it. Manual memory management as a daily craft, pointer arithmetic as a drill, hand-rolled allocators as a traditional requirement: these are depreciating production skills, and spending years on them is the two-year test failing gradually and visibly. The surface area of low-level is large and mostly irrelevant to the work most developers will actually do, and Brooks’s old split between accidental and essential complexity still maps onto it cleanly: the syntax and the boilerplate are accidental, and the accident is exactly what the model now absorbs.

Do teach them to read the foundation. Read a stack trace down to the frame that matters. Read a flame graph and point at the function that is eating the budget. Read a heap profile, an strace, a slow query log, a core dump. Read the source of the standard library they use every day, at least once, until the abstraction stops being magic. Reading is cheaper than writing, it transfers to every language and every model generation, and it builds exactly the four models above without demanding the years of production fluency the old curriculum required.

The rule of thumb is blunt and useful: enough low-level to debug, not enough to ship. A few focused weeks of C or Rust, or even a careful tour through how the managed language you already use actually executes, is enough to install the models for a working lifetime, provided the engineer keeps reading systems instead of reading only diffs. A career of writing C, in 2026, is overkill for most roles and a misallocation of the time that should be going into domain depth and judgment.

And for the small fraction of work that genuinely lives at the foundation, embedded, kernels, databases, runtimes, high-frequency paths, the calculus flips and fluency is still required. The point is not that nobody should write low-level code. The point is that “should every new developer learn to write low-level code” is the wrong question, asked about the wrong layer, and the answer, which is “no, but every developer should learn to read the machine,” is what the two camps keep talking past.

What to Do Next
#

If you hire or mentor new developers, stop using “do you know C” as a proxy for anything. It measures syntax, and syntax is cheap.

Instead, hand them a deliberately broken program, one with a memory or concurrency bug hidden behind a clean high-level interface, and watch what they do. The ones who can form a hypothesis about the layer underneath are the ones who can supervise a machine. The ones who can only describe the symptom to the model and accept its first confident answer are the ones who will ship that bug to production and then be unable to explain it.

If you are a new developer yourself, do not let the tools talk you out of the foundation. Generate the boilerplate, take the shortcut, and then, separately, on your own time, read the source of something you depend on until you can explain how it actually works. The generation is free. The understanding is not, and it is the only part of this profession that the next ten years will reward more, not less.

The debate between “learn everything low-level” and “writing code is dead” is two ways of staring at the surface. The surface is going away. The foundation is not. Prepare accordingly.

See also
#

References
#

  • Spolsky, “The Law of Leaky Abstractions” - the original framing for why every abstraction eventually fails at the layer underneath, which is where foundation knowledge pays
  • Wikipedia, “Theory of Constraints” - the framework for why automating code production relocates rather than removes the bottleneck, landing it on verification
  • Wikipedia, “No Silver Bullet” - Brooks’s split between accidental complexity (the syntax and boilerplate AI now handles) and essential complexity (the mental model of the problem it cannot)
  • Wikipedia, “Accidental complexity” - the distinction that lets you sort low-level trivia, which is accidental and depreciating, from low-level mental models, which are essential and compounding
  • Wikipedia, “Vibe coding” - the extreme of the “writing code is over” position, used here as the steelman argued against rather than a strawman
  • Willison, “Vibe coding” - a practitioner’s account of what you can and cannot safely delegate, and why supervision still requires understanding the output